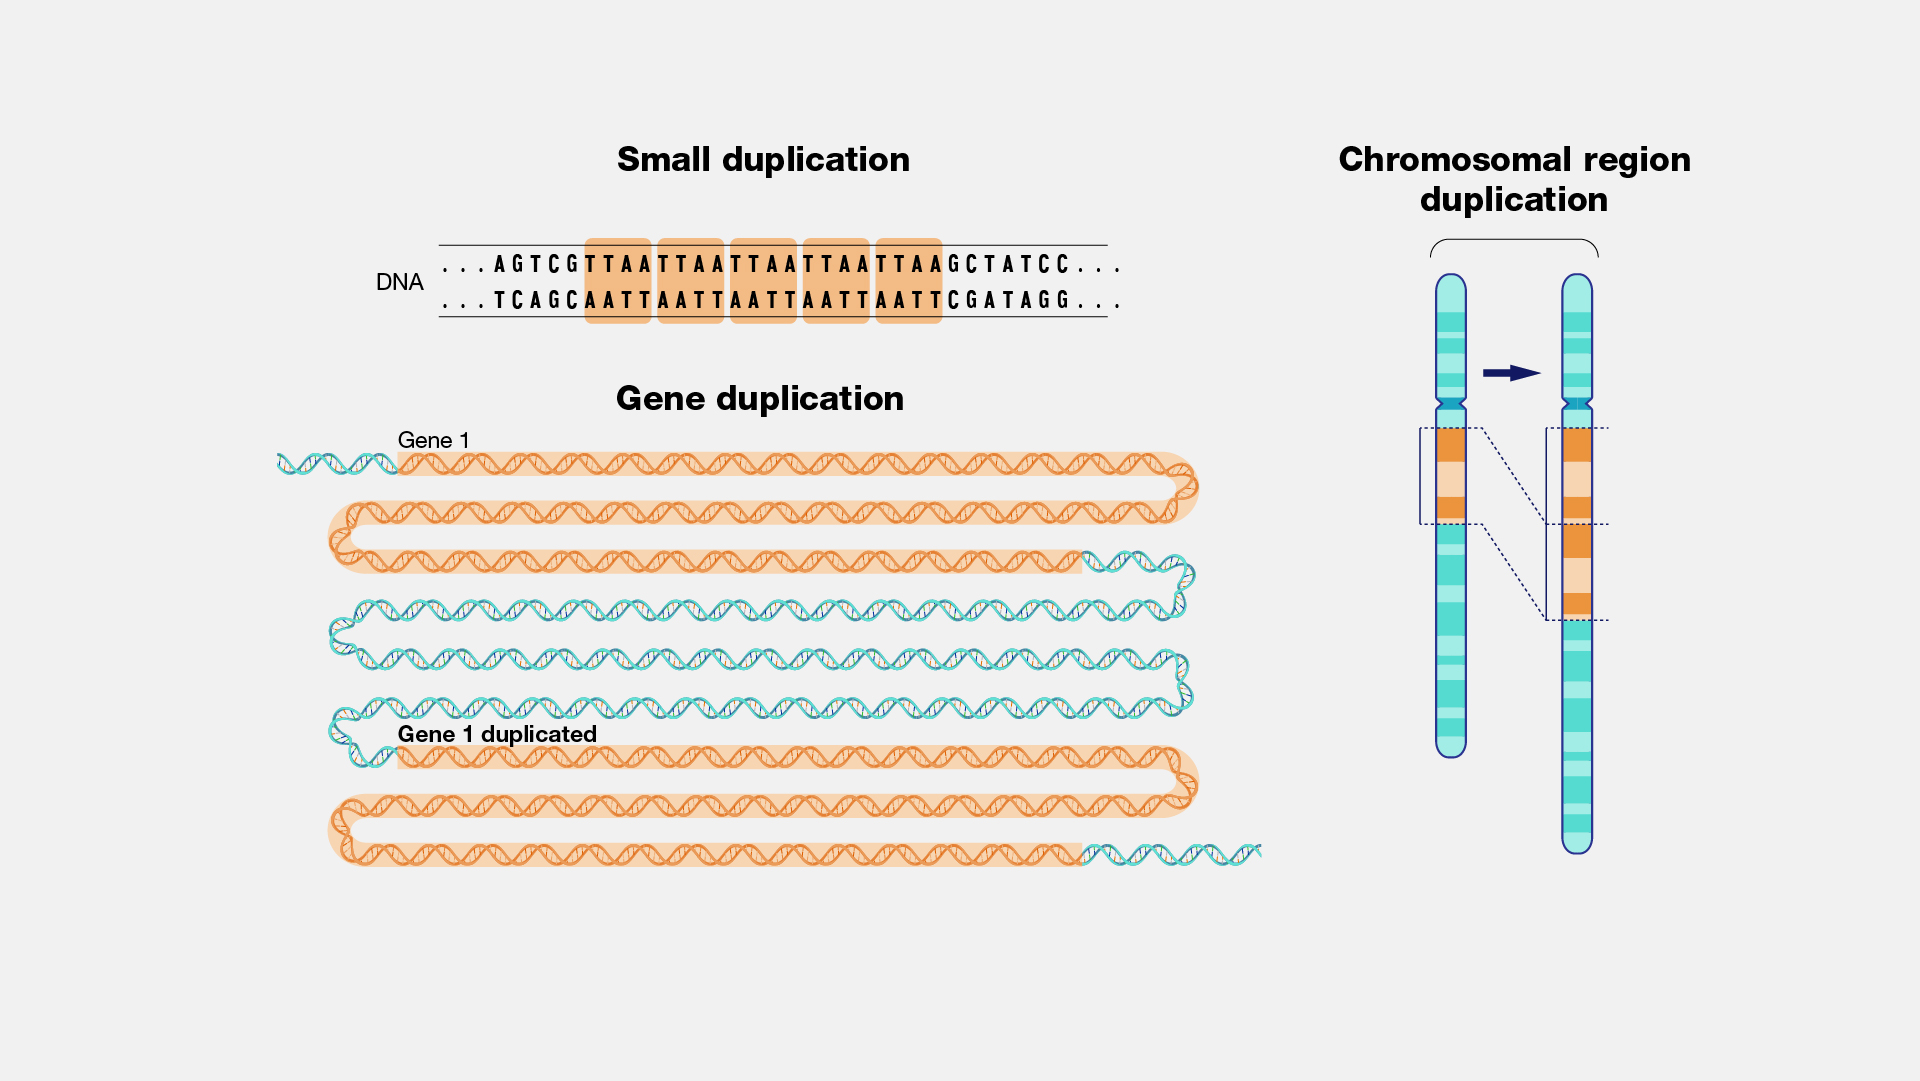
Practice · Scientific reasoning and quantitative skills

Design and evaluate research

Sources ↗

A study’s measurements, comparisons, recruitment, and ethical constraints determine what conclusions it can support.

Make the claim testable

A hypothesis predicts a relationship that observations could challenge. specify how constructs become manipulations or measurements: define memory as recall of a specified word list after a fixed delay, rather than merely saying memory improves. Identify the , , and comparison. A prediction should identify direction and conditions without redefining success after results appear. A commonly specifies no difference or association for a population parameter; it is not a claim that every individual behaves identically.

Source: 2.2 Approaches to Research · 1.2 Data, Sampling, and Variation in Data and Sampling · 2.4 Ethics · 2.3 Analyzing Findings

Match design to the inference

Experiments manipulate exposure; can balance on average and support causal inference when implementation is sound. Observational studies measure naturally occurring exposure. Cross-sectional designs measure groups at one time; longitudinal designs follow change and can establish time order but face . give depth with limited generalizability. interviews examine meanings and experiences using systematic interpretation; they are not failed experiments. Ethical or practical constraints can make an experiment impossible, so causal claims must reflect available evidence.

Source: 2.2 Approaches to Research · 1.2 Data, Sampling, and Variation in Data and Sampling · 2.4 Ethics · 2.3 Analyzing Findings

Control alternative explanations

A is associated with the exposure and independently affects the outcome. , matching, , standardized procedures, and appropriate control groups address different threats. A placebo can control expectancy; a positive control tests whether an can detect a known effect; a negative control estimates background or contamination. concerns consistency; concerns whether the measure or inference captures its intended target. Repeating a biased measurement can be reliable without being accurate. Randomization does not guarantee balance in one small sample.

Source: 2.2 Approaches to Research · 1.2 Data, Sampling, and Variation in Data and Sampling · 2.4 Ethics · 2.3 Analyzing Findings

Separate selection from assignment

A sample is observed; a population is the group about which inference is intended. Probability sampling can support population representation, whereas convenience or volunteer sampling may systematically omit people. allocates sampled participants to conditions and supports internal comparison; it does not make a representative. Nonresponse and can introduce selection bias after recruitment. A larger sample reduces some sampling variability but does not automatically repair a systematically biased selection process.

Source: 2.2 Approaches to Research · 1.2 Data, Sampling, and Variation in Data and Sampling · 2.4 Ethics · 2.3 Analyzing Findings

Protect participants and report honestly

Research requires respect for persons, a proportionate balance of benefits and harms, and fair participant selection. Informed consent should explain relevant procedures and risks while allowing voluntary ; privacy and confidentiality are related but distinct protections. Deception requires justification and appropriate oversight and debriefing. Animal work also requires justified use and humane care. Report methods, exclusions, uncertainty, and negative findings honestly; fabricate neither data nor authorship. Ethical review does not itself establish that a study’s conclusions are statistically or causally valid.

Source: 2.2 Approaches to Research · 1.2 Data, Sampling, and Variation in Data and Sampling · 2.4 Ethics · 2.3 Analyzing Findings

Practice and reasoning

Question. A campus study lets volunteers choose caffeine or water before a memory test. The caffeine group scores higher. Identify a , improve causal inference, and explain why would not guarantee generalization to all adults.

Show reasoning

Sleep loss could influence beverage choice and memory. to matched, blinded conditions with a standardized dose and test would address several alternative explanations, subject to appropriate participant protections. does not change who volunteered: campus volunteers can differ from the wider adult population. Sampling and assignment solve different problems.

Source: 2.2 Approaches to Research · 1.2 Data, Sampling, and Variation in Data and Sampling · 2.4 Ethics · 2.3 Analyzing Findings

2.2 Approaches to Research — figures and tables
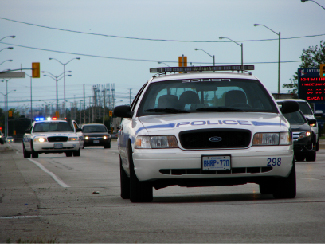
A photograph shows two police cars driving, one with its lights flashing.
Figure 2.7 — 2.2 Approaches to Research

Figure 2.7 Seeing a police car behind you would probably affect your driving behavior. (credit: Michael Gil)

Rose M. Spielman, William J. Jenkins, and Marilyn D. Lovett, Psychology 2E, OpenStax. (credit: Michael Gil) · CC BY-NC-SA 4.0 · Original image ↗ · Access for free ↗
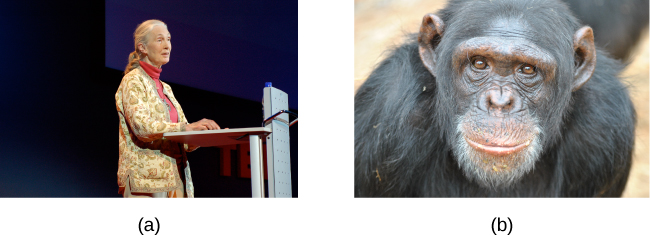
(a) A photograph shows Jane Goodall speaking from a lectern. (b) A photograph shows a chimpanzee’s face.
Figure 2.8 — 2.2 Approaches to Research

Figure 2.8 (a) Jane Goodall made a career of conducting naturalistic observations of (b) chimpanzee behavior. (credit “Jane Goodall”: modification of work by Erik Hersman; “chimpanzee”: modification of work by “Afrika Force”/Flickr.com)

Rose M. Spielman, William J. Jenkins, and Marilyn D. Lovett, Psychology 2E, OpenStax. (credit “Jane Goodall”: modification of work by Erik Hersman; “chimpanzee”: modification of work by “Afrika Force”/Flickr.com) · CC BY-NC-SA 4.0 · Original image ↗ · Access for free ↗
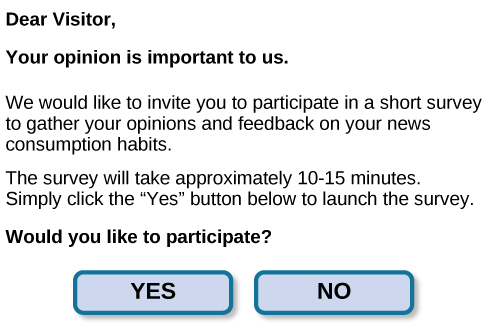
A sample online survey reads, “Dear visitor, your opinion is important to us. We would like to invite you to participate in a short survey to gather your opinions and feedback on your news consumption habits. The survey will take approximately 10-15 minutes. Simply click the “Yes” button below to launch the survey. Would you like to participate?” Two buttons are labeled “yes” and “no.”
Figure 2.9 — 2.2 Approaches to Research

Figure 2.9 Surveys can be administered in a number of ways, including electronically administered research, like the survey shown here. (credit: Robert Nyman)

Rose M. Spielman, William J. Jenkins, and Marilyn D. Lovett, Psychology 2E, OpenStax. (credit: Robert Nyman) · CC BY-NC-SA 4.0 · Original image ↗ · Access for free ↗
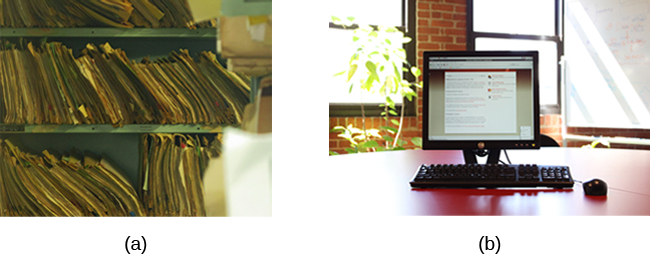
(a) A photograph shows stacks of paper files on shelves. (b) A photograph shows a computer.
Figure 2.10 — 2.2 Approaches to Research

Figure 2.10 A researcher doing archival research examines records, whether archived as a (a) hardcopy or (b) electronically. (credit “paper files”: modification of work by “Newtown graffiti”/Flickr; “computer”: modification of work by INPIVIC Family/Flickr)

Rose M. Spielman, William J. Jenkins, and Marilyn D. Lovett, Psychology 2E, OpenStax. (credit “paper files”: modification of work by “Newtown graffiti”/Flickr; “computer”: modification of work by INPIVIC Family/Flickr) · CC BY-NC-SA 4.0 · Original image ↗ · Access for free ↗
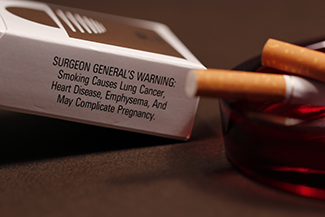
A photograph shows pack of cigarettes and cigarettes in an ashtray. The pack of cigarettes reads, “Surgeon general’s warning: smoking causes lung cancer, heart disease, emphysema, and may complicate pregnancy.”
Figure 2.11 — 2.2 Approaches to Research

Figure 2.11 Longitudinal research like the CPS-3 help us to better understand how smoking is associated with cancer and other diseases. (credit: CDC/Debora Cartagena)

Rose M. Spielman, William J. Jenkins, and Marilyn D. Lovett, Psychology 2E, OpenStax. (credit: CDC/Debora Cartagena) · CC BY-NC-SA 4.0 · Original image ↗ · Access for free ↗

Source: 2.2 Approaches to Research

1.2 Data, Sampling, and Variation in Data and Sampling — figures and tables
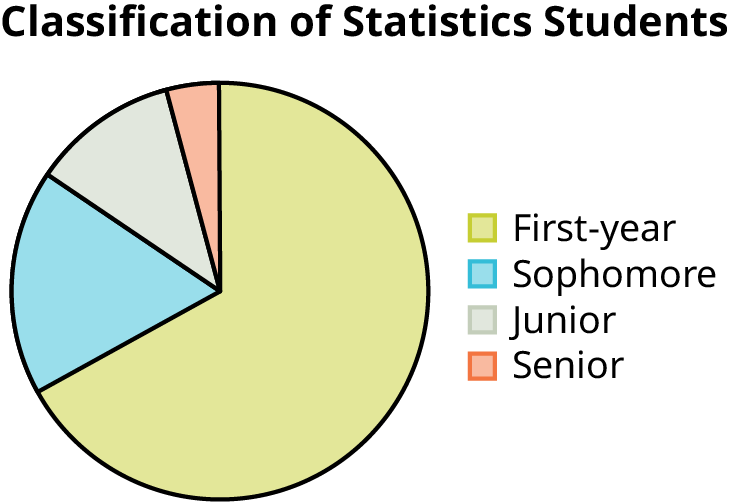
This is a pie chart showing the class classification of statistics students. The chart has 4 sections labeled Freshman, Sophomore, Junior, Senior. A question is asked below the pie chart: what type of data does this graph show?
Figure 1.3 — 1.2 Data, Sampling, and Variation in Data and Sampling

Figure 1.3

Barbara Illowsky and Susan Dean, Introductory Statistics 2E, OpenStax. · CC BY-NC-SA 4.0 · Original image ↗ · Access for free ↗
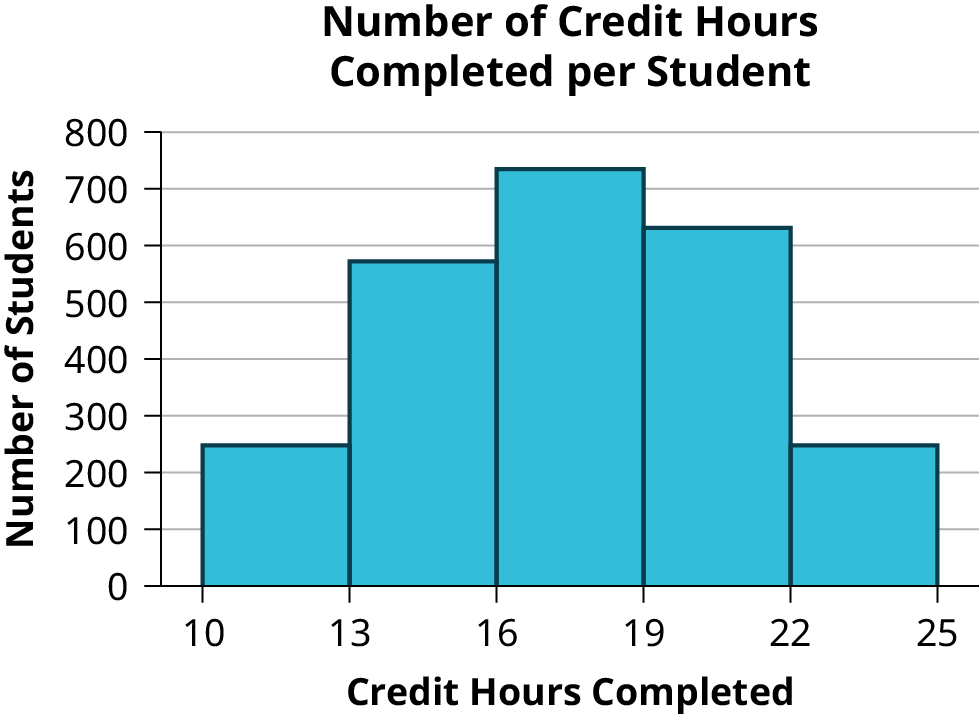
This histogram consists of 5 bars with the x-axis marked at intervals of 3 from 10 to 25, and the y-axis in increments of 100 from 0 to 800. The height of bars shows the number of students in each interval. Interval 10 to 13 is at 250, interval 13 to 16 is at 580, interval 16 to 19 is at 720, interval 19 to 22 is at 620, and interval 22 to 25 is at 250.
Figure 1.4 — 1.2 Data, Sampling, and Variation in Data and Sampling

Figure 1.4

Barbara Illowsky and Susan Dean, Introductory Statistics 2E, OpenStax. · CC BY-NC-SA 4.0 · Original image ↗ · Access for free ↗
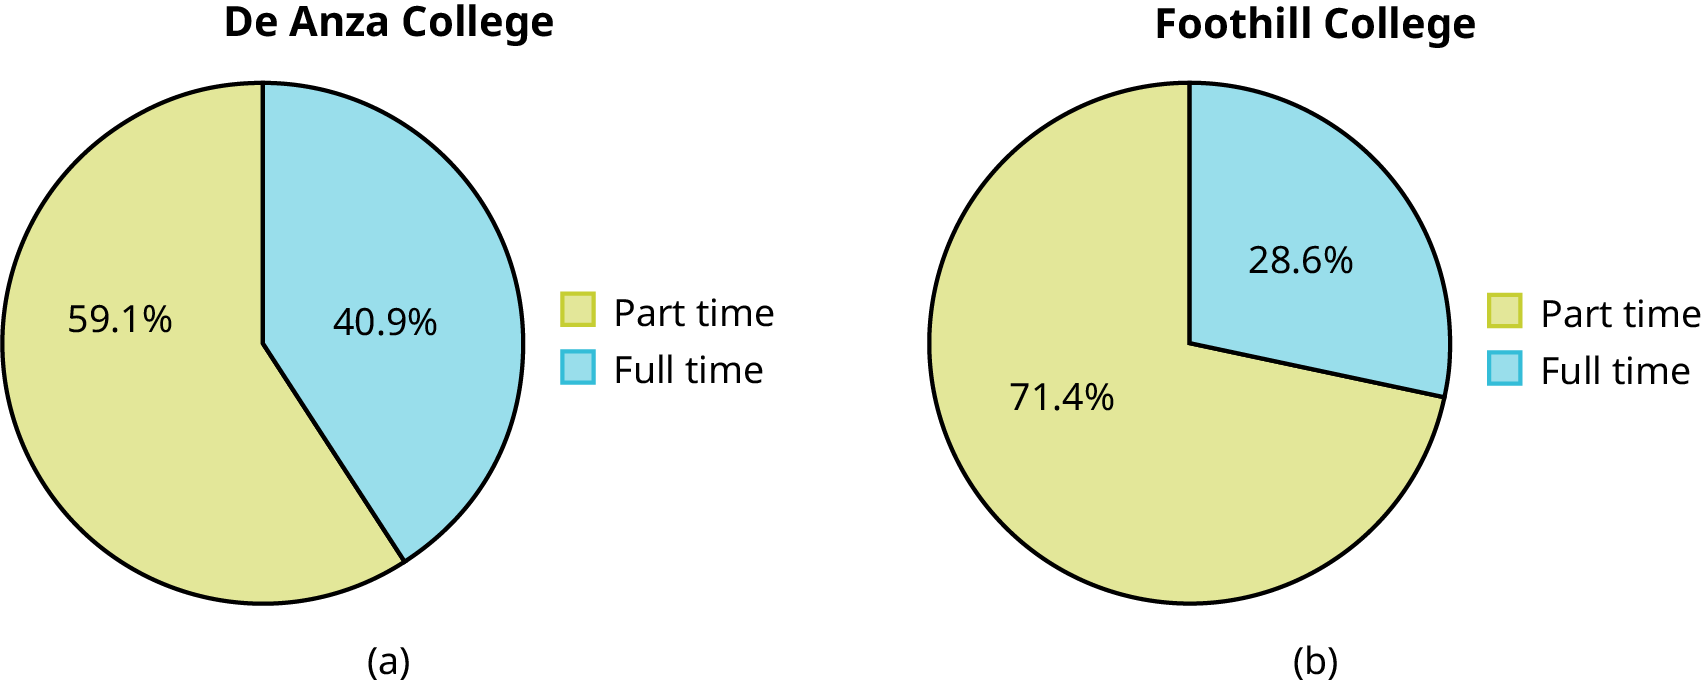
Side-by-side pie charts showing the distribution of part time and full time students. The chart on the left is titled De Anza college. It is divided into two sections showing that part time students represent 59.1% of the population and full time students make up 40.9%. The chart on the right is titled Foothill college. It is divided into two sections showing that part time students represent 71.4% of the population and full time students make up 28.6%.
Figure 1.5 — 1.2 Data, Sampling, and Variation in Data and Sampling

Figure 1.5

Barbara Illowsky and Susan Dean, Introductory Statistics 2E, OpenStax. · CC BY-NC-SA 4.0 · Original image ↗ · Access for free ↗
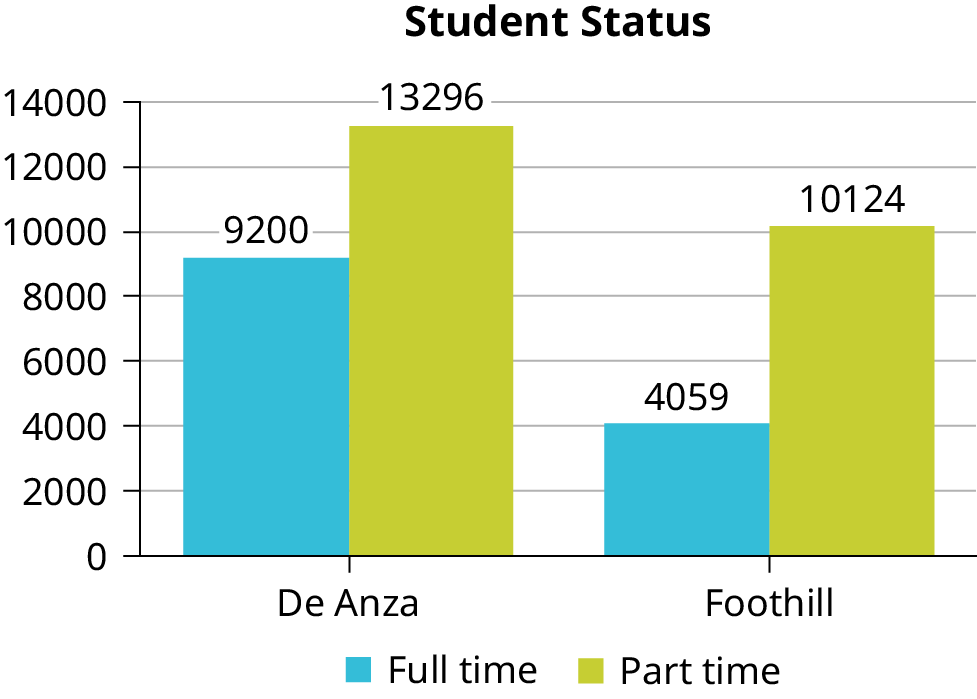
A bar chart titled 'Student Status' shows student numbers for De Anza and Foothill colleges. De Anza has 9,200 full-time and 13,296 part-time students. Foothill has 4,059 full-time and 10,124 part-time students.
Figure 1.6 — 1.2 Data, Sampling, and Variation in Data and Sampling

Figure 1.6

Barbara Illowsky and Susan Dean, Introductory Statistics 2E, OpenStax. · CC BY-NC-SA 4.0 · Original image ↗ · Access for free ↗
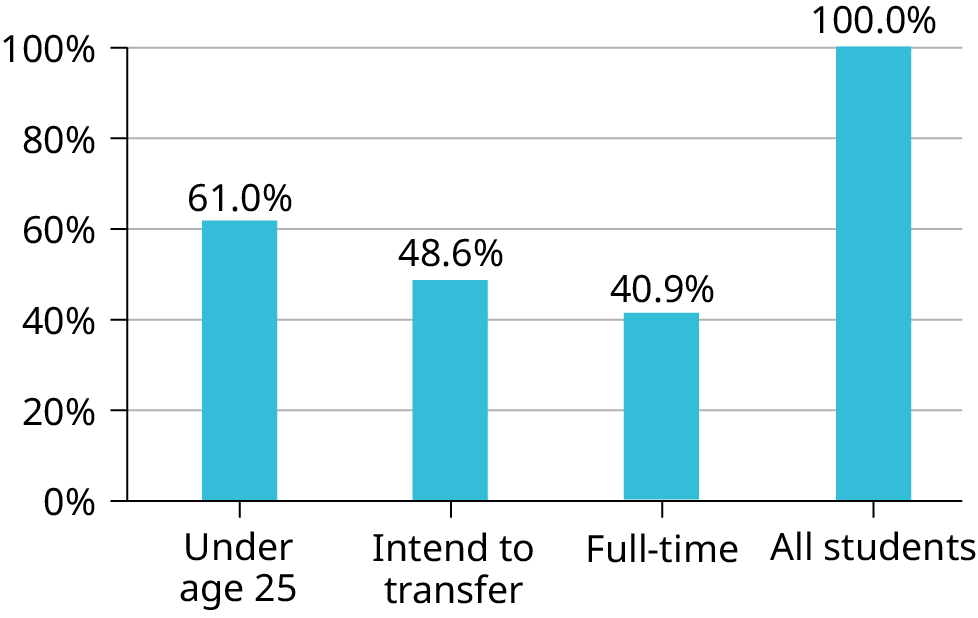
A bar graph. The vertical axis marks values from 0% to 100% in intervals of 20%. The horizontal axis categories are Under age 25 (height of bar shows 61.0%), Intend to transfer (height of bar shows 48.6%), Full-time (height of bar shows 40.9%), and All students (height of bar shows 100%).
Figure 1.7 — 1.2 Data, Sampling, and Variation in Data and Sampling

Figure 1.7

Barbara Illowsky and Susan Dean, Introductory Statistics 2E, OpenStax. · CC BY-NC-SA 4.0 · Original image ↗ · Access for free ↗
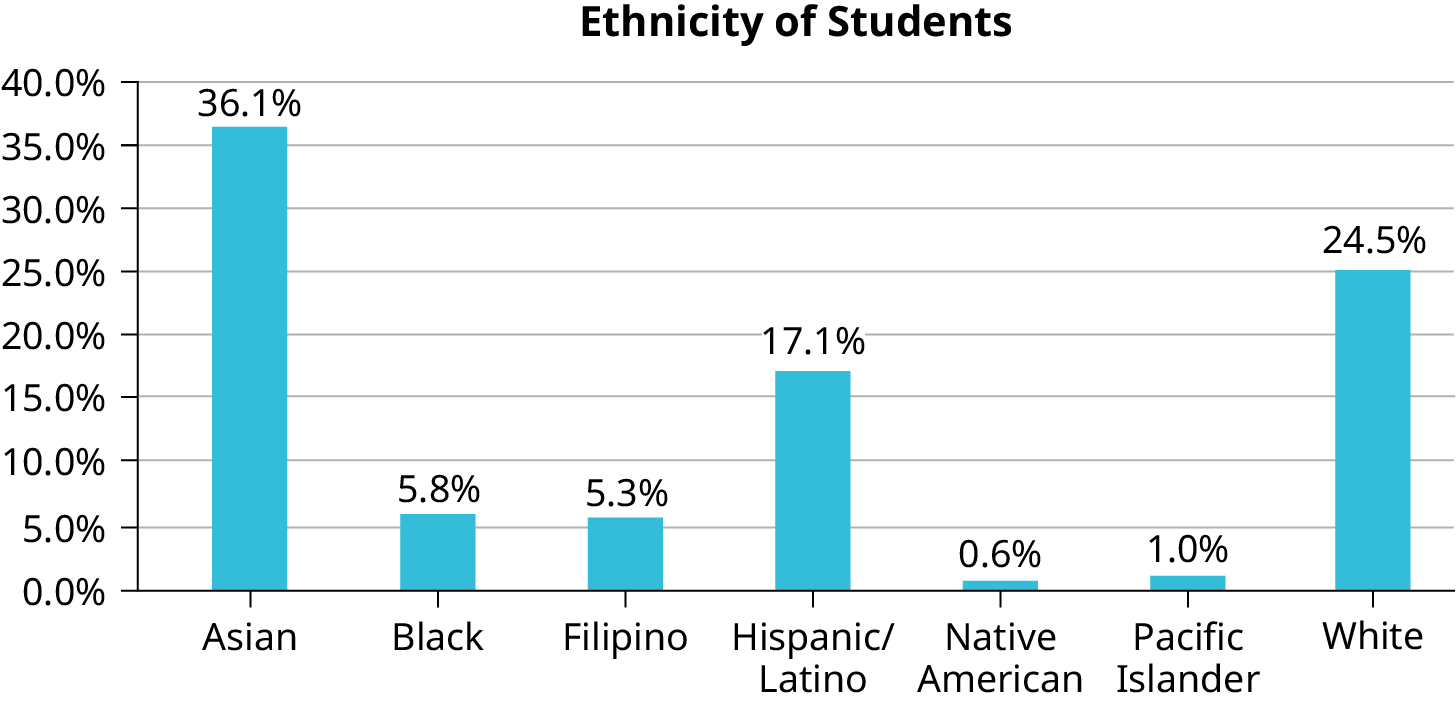
A bar graph showing ethnicity of students. The vertical axis marks values from 0.0% to 40.0% in intervals of 5.0%. The horizontal axis categories are Asian (height of bar shows 36.1%), Black (height of bar shows 5.8%), Filipino (height of bar shows 5.3%), Hispanic/Latino (height of bar shows 17.1%), Native American (height of bar shows 0.6%), Pacific Islander (height of bar shows 1.0%),and White (height of bar shows 24.5%).
Figure 1.8 — 1.2 Data, Sampling, and Variation in Data and Sampling

Figure 1.8

Barbara Illowsky and Susan Dean, Introductory Statistics 2E, OpenStax. · CC BY-NC-SA 4.0 · Original image ↗ · Access for free ↗
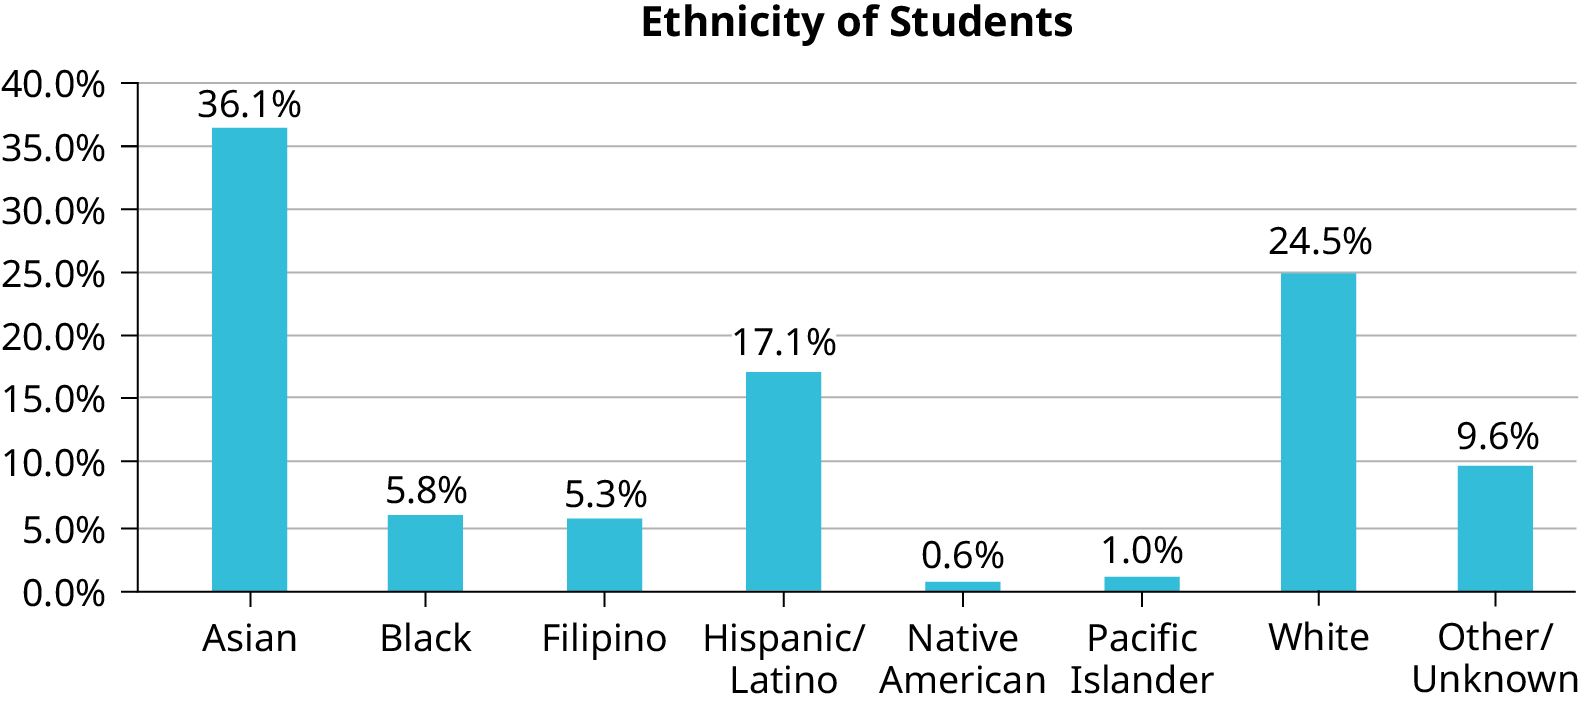
Bar graph consisting of 8 bars with values matching the given data. Horizontal axis has all ethinicity of student. Vertical axis ranges ffrom 0 to 40 percent in increments of 5 percent.
Figure 1.9 — 1.2 Data, Sampling, and Variation in Data and Sampling

Figure 1.9 Bar Graph with Other/Unknown Category

Barbara Illowsky and Susan Dean, Introductory Statistics 2E, OpenStax. · CC BY-NC-SA 4.0 · Original image ↗ · Access for free ↗
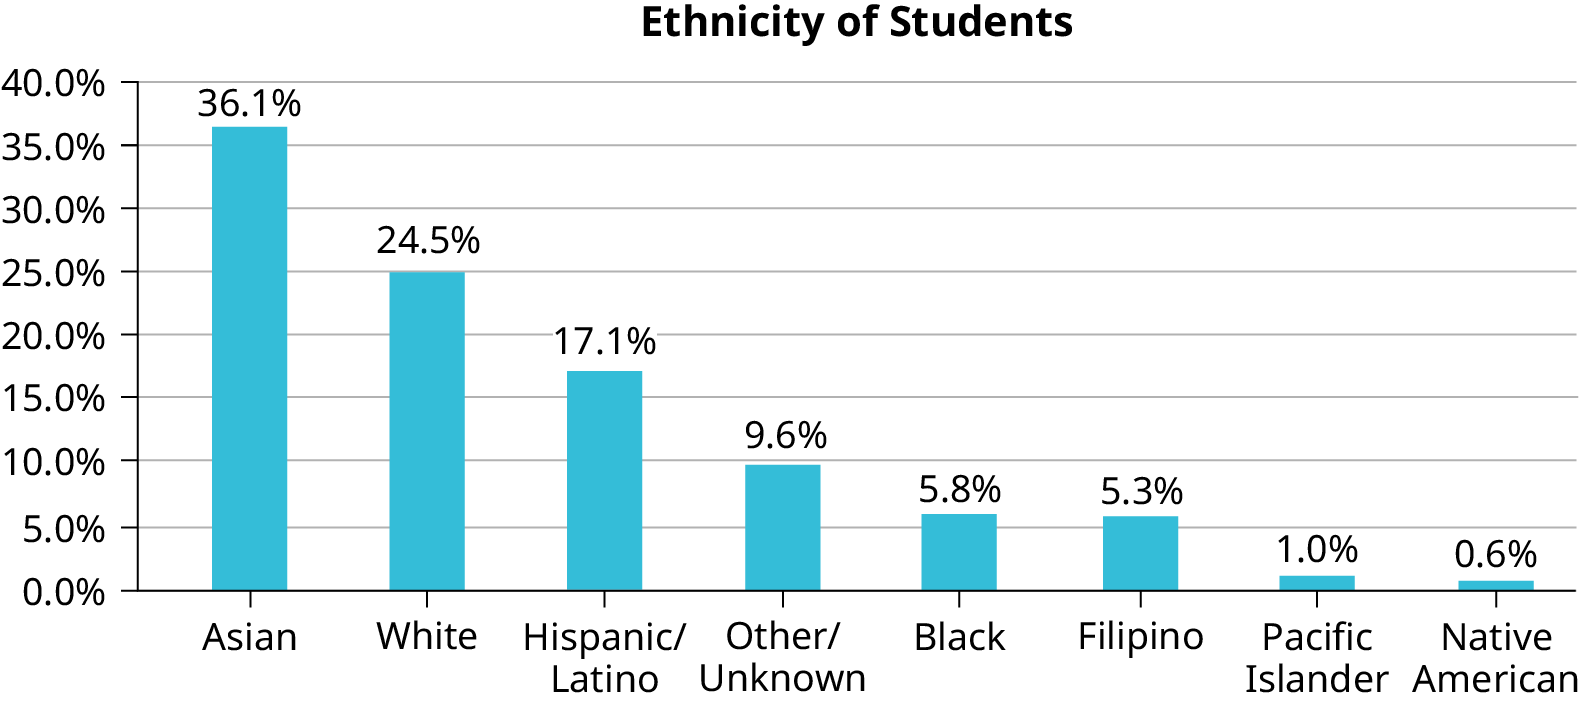
A Pareto chart is a bar graph with the bars ordered from greatest height to least. This one shows ethnicity of students. The vertical axis marks values from 0.0% to 40.0% in intervals of 5.0%. The horizontal axis categories are Asian (height of bar shows 36.1%), White (height of bar shows 24.5%), Hispanic/Latino (height of bar shows 17.1%), Other/Unknown (height of bar shows 9.6%), Black (height of bar shows 5.8%), Filipino (height of bar shows 5.3%), Pacific Islander (height of bar shows 1.0%), and Native American (height of bar shows 0.6%).
Figure 1.10 — 1.2 Data, Sampling, and Variation in Data and Sampling

Figure 1.10 Pareto Chart With Bars Sorted by Size

Barbara Illowsky and Susan Dean, Introductory Statistics 2E, OpenStax. · CC BY-NC-SA 4.0 · Original image ↗ · Access for free ↗
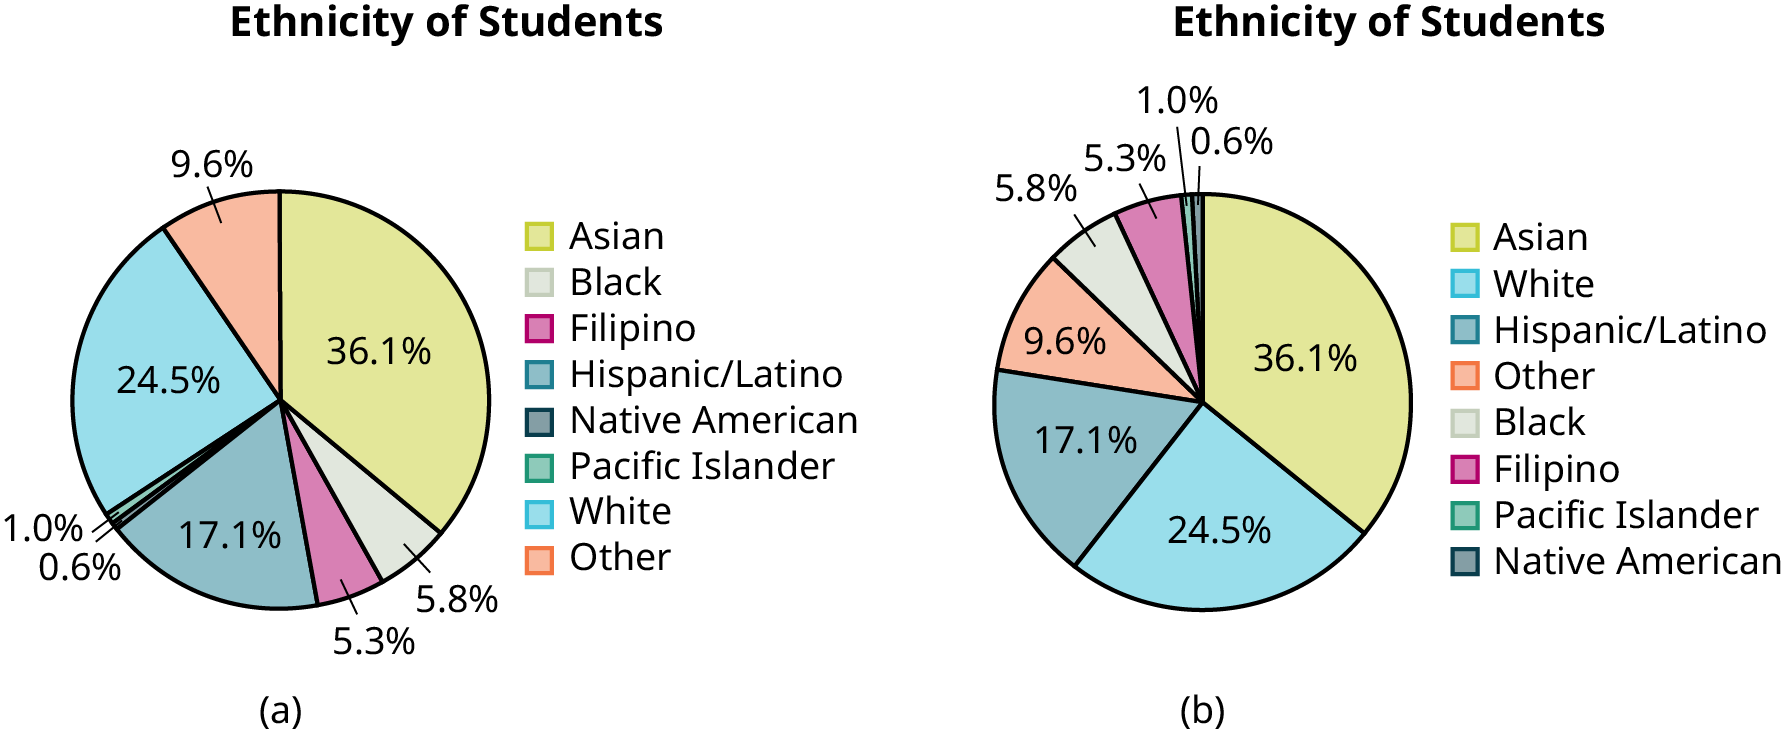
Two pie charts are titled Ethnicity of Students. Chart (a) The sections of the chart are ordered alphabetically. Clockwise from the top, the sections show that Asian students make up 36.1% of students, Black 5.8%, Filipino 5.3%, Hispanic/Latino 17.1%, Native American 0.6%, Pacific Islander 1.0%, White 24.5%, and Other 9.6%. Chart (b) This is the same data as shown in chart (a), but the sections of the chart are now ordered from greatest area to least. Clockwise from the top, the sections show that Asian students make up 36.1% of students, White 24.5%, Hispanic/Latino 17.1%, Other 9.6%, Black 5.8%, Filipino 5.3%, Pacific Islander 1.0%, and Native American 0.6%.
Figure 1.11 — 1.2 Data, Sampling, and Variation in Data and Sampling

Figure 1.11

Barbara Illowsky and Susan Dean, Introductory Statistics 2E, OpenStax. · CC BY-NC-SA 4.0 · Original image ↗ · Access for free ↗
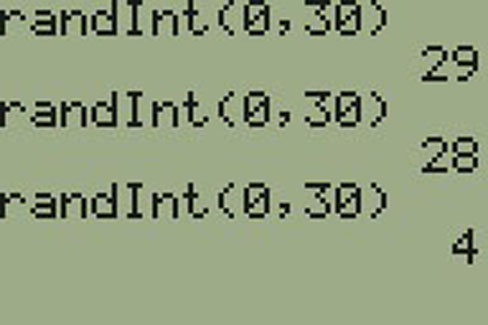
A calculator screen shows the following set on separate lines: randInt (0, 30); 29; randInt (0, 30); 28; randInt (0, 30); 4.
Figure 1.12 — 1.2 Data, Sampling, and Variation in Data and Sampling

Figure 1.12

Barbara Illowsky and Susan Dean, Introductory Statistics 2E, OpenStax. · CC BY-NC-SA 4.0 · Original image ↗ · Access for free ↗
De Anza College Foothill College
Number Percent Number Percent
Full-time 9,200 40.9% Full-time 4,059 28.6%
Part-time 13,296 59.1% Part-time 10,124 71.4%
Total 22,496 100% Total 14,183 100%

Table 1.3 Most Recent Spring Quarter. Barbara Illowsky and Susan Dean, Introductory Statistics 2E, OpenStax.

Characteristic/Category Percent
Full-Time Students 40.9%
Students who intend to transfer to a 4-year educational institution 48.6%
Students under age 25 61.0%
TOTAL 150.5%

Table 1.4 De Anza College Most Recent Spring Quarter. Barbara Illowsky and Susan Dean, Introductory Statistics 2E, OpenStax.

Frequency Percent
Asian 8,794 36.1%
Black 1,412 5.8%
Filipino 1,298 5.3%
Hispanic/Latino 4,180 17.1%
Native American 146 0.6%
Pacific Islander 236 1.0%
White 5,978 24.5%
TOTAL 22,044 out of 24,382 90.4% out of 100%

Table 1.5 Ethnicity of Students at De Anza College in the Most Recent Fall Term. Barbara Illowsky and Susan Dean, Introductory Statistics 2E, OpenStax.

ID Name ID Name ID Name
00 Anselmo 11 King 21 Roquero
01 Bautista 12 Legeny 22 Roth
02 Bayani 13 Lundquist 23 Rowell
03 Cheng 14 Macierz 24 Salangsang
04 Cuarismo 15 Motogawa 25 Slade
05 Cuningham 16 Okimoto 26 Stratcher
06 Fontecha 17 Patel 27 Tallai
07 Hong 18 Price 28 Tran
08 Hoobler 19 Quizon 29 Wai
09 Jiao 20 Reyes 30 Wood
10 Khan

Table 1.6 Class Roster. Barbara Illowsky and Susan Dean, Introductory Statistics 2E, OpenStax.

#1 #2 #3 #4 #5 #6
5 7 10 9 8 3
10 5 9 8 7 6
9 10 8 6 7 9
9 10 10 9 8 9
7 8 9 5 7 4
9 9 9 10 8 7
7 7 10 9 8 8
8 8 9 10 8 8
9 7 8 7 7 8
8 8 10 9 8 7

Table 1.7. Barbara Illowsky and Susan Dean, Introductory Statistics 2E, OpenStax.

Face on Die Frequency
1
2
3
4
5
6

Table 1.8 First Experiment (20 rolls). Barbara Illowsky and Susan Dean, Introductory Statistics 2E, OpenStax.

Face on Die Frequency
1
2
3
4
5
6

Table 1.9 Second Experiment (20 rolls). Barbara Illowsky and Susan Dean, Introductory Statistics 2E, OpenStax.

Source: 1.2 Data, Sampling, and Variation in Data and Sampling

2.4 Ethics — figures and tables
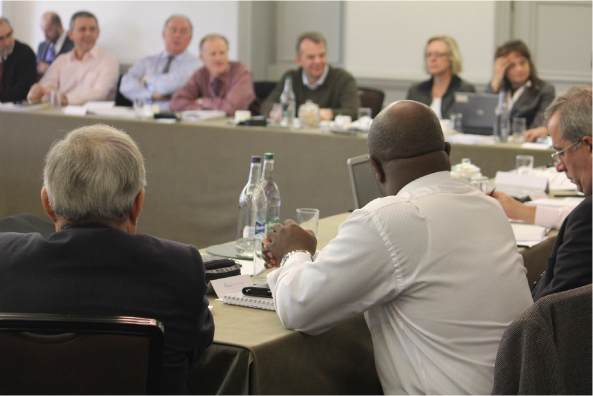
A photograph shows a group of people seated around tables in a meeting room.
Figure 2.20 — 2.4 Ethics

Figure 2.20 An institution’s IRB meets regularly to review experimental proposals that involve human participants. (credit: International Hydropower Association/Flickr)

Rose M. Spielman, William J. Jenkins, and Marilyn D. Lovett, Psychology 2E, OpenStax. (credit: International Hydropower Association/Flickr) · CC BY-NC-SA 4.0 · Original image ↗ · Access for free ↗
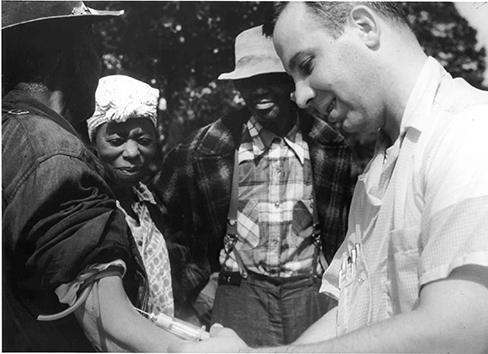
A photograph shows a person administering an injection.
Figure 2.21 — 2.4 Ethics

Figure 2.21 A participant in the Tuskegee Syphilis Study receives an injection.

Rose M. Spielman, William J. Jenkins, and Marilyn D. Lovett, Psychology 2E, OpenStax. · CC BY-NC-SA 4.0 · Original image ↗ · Access for free ↗
A photograph shows a rat.
Figure 2.22 — 2.4 Ethics

Figure 2.22 Rats, like the one shown here, often serve as the subjects of animal research.

Rose M. Spielman, William J. Jenkins, and Marilyn D. Lovett, Psychology 2E, OpenStax. · CC BY-NC-SA 4.0 · Original image ↗ · Access for free ↗

Source: 2.4 Ethics

2.3 Analyzing Findings — figures and tables
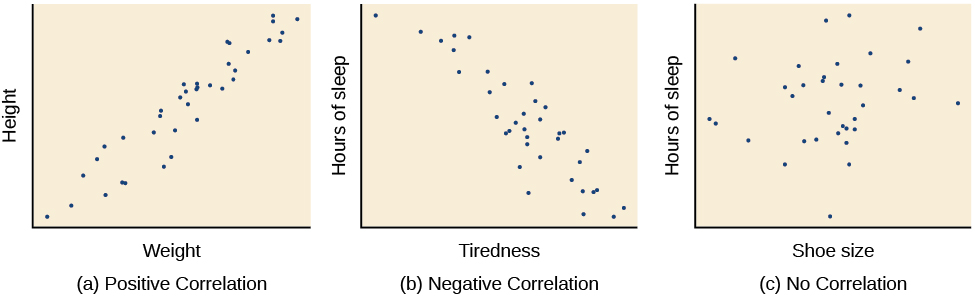
Three scatterplots are shown. Scatterplot (a) is labeled “positive correlation” and shows scattered dots forming a rough line from the bottom left to the top right; the x-axis is labeled “weight” and the y-axis is labeled “height.” Scatterplot (b) is labeled “negative correlation” and shows scattered dots forming a rough line from the top left to the bottom right; the x-axis is labeled “tiredness” and the y-axis is labeled “hours of sleep.” Scatterplot (c) is labeled “no correlation” and shows scattered dots having no pattern; the x-axis is labeled “shoe size” and the y-axis is labeled “hours of sleep.”
Figure 2.12 — 2.3 Analyzing Findings

Figure 2.12 Scatterplots are a graphical view of the strength and direction of correlations. The stronger the correlation, the closer the data points are to a straight line. In these examples, we see that there is (a) a positive correlation between weight and height, (b) a negative correlation between tiredness and hours of sleep, and (c) no correlation between shoe size and hours of sleep.

Rose M. Spielman, William J. Jenkins, and Marilyn D. Lovett, Psychology 2E, OpenStax. · CC BY-NC-SA 4.0 · Original image ↗ · Access for free ↗
A photograph shows a bowl of cereal.
Figure 2.13 — 2.3 Analyzing Findings

Figure 2.13 Does eating cereal really cause someone to be healthier? (credit: Tim Skillern)

Rose M. Spielman, William J. Jenkins, and Marilyn D. Lovett, Psychology 2E, OpenStax. (credit: Tim Skillern) · CC BY-NC-SA 4.0 · Original image ↗ · Access for free ↗
A photograph shows the moon.
Figure 2.14 — 2.3 Analyzing Findings

Figure 2.14 Many people believe that a full moon makes people behave oddly. (credit: Cory Zanker)

Rose M. Spielman, William J. Jenkins, and Marilyn D. Lovett, Psychology 2E, OpenStax. (credit: Cory Zanker) · CC BY-NC-SA 4.0 · Original image ↗ · Access for free ↗
Many rows of students are in a classroom. One student has an open laptop on his desk.
Figure 2.15 — 2.3 Analyzing Findings

Figure 2.15 How might the use of technology in the classroom impact learning? (credit: modification of work by Nikolay Georgiev/Pixabay)

Rose M. Spielman, William J. Jenkins, and Marilyn D. Lovett, Psychology 2E, OpenStax. (credit: modification of work by Nikolay Georgiev/Pixabay) · CC BY-NC-SA 4.0 · Original image ↗ · Access for free ↗
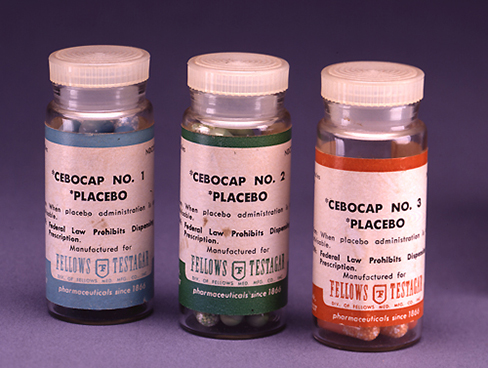
A photograph shows three glass bottles of pills labeled as placebos.
Figure 2.16 — 2.3 Analyzing Findings

Figure 2.16 Providing the control group with a placebo treatment protects against bias caused by expectancy. (credit: Elaine and Arthur Shapiro)

Rose M. Spielman, William J. Jenkins, and Marilyn D. Lovett, Psychology 2E, OpenStax. (credit: Elaine and Arthur Shapiro) · CC BY-NC-SA 4.0 · Original image ↗ · Access for free ↗
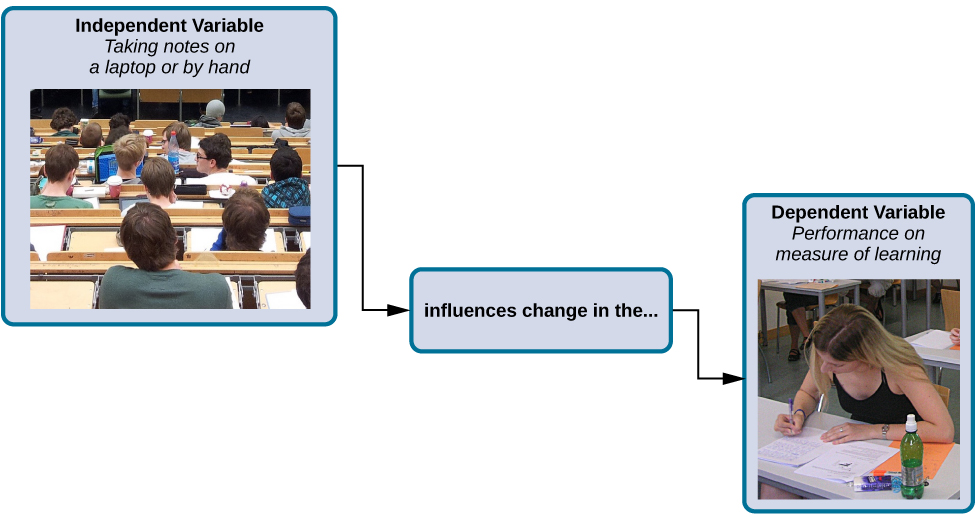
A box labeled “independent variable: taking notes on a laptop or by hand” contains a photograph of a classroom of students with an open laptop on one student's desk. An arrow labeled “influences change in the…” leads to a second box. The second box is labeled “dependent variable: performance on measure of learning” and has a photograph of a student at a desk, taking a test.
Figure 2.17 — 2.3 Analyzing Findings

Figure 2.17 In an experiment, manipulations of the independent variable are expected to result in changes in the dependent variable. (credit: “classroom” modification of work by Nikolay Georgiev/Pixabay; credit “note taking”: modification of work by KF/Wikimedia)

Rose M. Spielman, William J. Jenkins, and Marilyn D. Lovett, Psychology 2E, OpenStax. (credit: “classroom” modification of work by Nikolay Georgiev/Pixabay; credit “note taking”: modification of work by KF/Wikimedia) · CC BY-NC-SA 4.0 · Original image ↗ · Access for free ↗
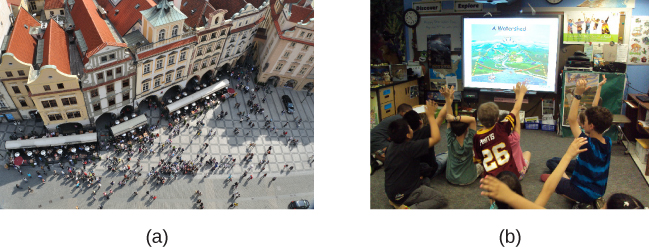
(a) A photograph shows an aerial view of crowds on a street. (b) A photograph shows s small group of children.
Figure 2.18 — 2.3 Analyzing Findings

Figure 2.18 Researchers may work with (a) a large population or (b) a sample group that is a subset of the larger population. (credit “crowd”: modification of work by James Cridland; credit “students”: modification of work by Laurie Sullivan)

Rose M. Spielman, William J. Jenkins, and Marilyn D. Lovett, Psychology 2E, OpenStax. (credit “crowd”: modification of work by James Cridland; credit “students”: modification of work by Laurie Sullivan) · CC BY-NC-SA 4.0 · Original image ↗ · Access for free ↗
A photograph shows a child being given an oral vaccine.
Figure 2.19 — 2.3 Analyzing Findings

Figure 2.19 Some people still think vaccinations cause autism. (credit: modification of work by UNICEF Sverige)

Rose M. Spielman, William J. Jenkins, and Marilyn D. Lovett, Psychology 2E, OpenStax. (credit: modification of work by UNICEF Sverige) · CC BY-NC-SA 4.0 · Original image ↗ · Access for free ↗

Source: 2.3 Analyzing Findings

134 terms, alphabetically ordered

Acid · ·

In the Brønsted–Lowry model, a substance that can donate a . Acidic have a higher activity than water.

Read explanation · OpenStax ↗
Activation energy ·

The energy barrier that must overcome to reach a and undergo .

Read explanation · OpenStax ↗
Adenosine triphosphate

An energy-carrying ; its powers many cellular processes, including cycles.

Read explanation · OpenStax ↗
Alpha carbon · ·

The central carbon next to the carboxyl carbon. In a standard it binds an , hydrogen, and .

Read explanation · OpenStax ↗
Amide · · ·

A group containing a carbon bonded to nitrogen. are amide linkages.

Read explanation · OpenStax ↗
Amino acid

A building block containing amino and and a characteristic .

Read explanation · OpenStax ↗
Amino acid residue · ·

The part of an incorporated into a chain. Residue can also describe another building block within a larger .

Read explanation · OpenStax ↗
Amino group · · ·

A nitrogen-containing . A free ’s amino group is typically (NH₃⁺) near physiological ; ’s ring nitrogen is an exception to this formula.

Read explanation · OpenStax ↗
Amphipathic

Having both a region and a region, as in a or .

Read explanation · OpenStax ↗
Analytical standard ·

A material with a known identity or amount used to compare or calibrate measurements.

Read explanation · Agilent ↗
Aqueous solution ·

A in which water is the .

Read explanation · OpenStax ↗
Assay

A procedure used to detect a substance or measure its amount, activity, or another property.

Read explanation · Thermo Fisher ↗
Atom

The smallest unit of an element that retains its chemical identity; it has a surrounded by .

Read explanation · OpenStax ↗
attachment

Enduring emotional bond and expectations about another’s availability and responsiveness.

Read explanation · OpenStax ↗
attitude

Evaluation of an object, person, issue, or behavior.

Read explanation · OpenStax ↗
attrition

Loss of participants or observations during follow-up.

Read explanation · OpenStax ↗
Biomolecule

A made by or involved in living systems, including , , , and .

Read explanation · OpenStax ↗
blinding

Withholding relevant treatment or group information to reduce expectancy or assessment bias.

Read explanation · OpenStax ↗
Blotting ·

Transfer of separated or to a so a specific target can be detected.

Read explanation · Thermo Fisher ↗
Brønsted–Lowry base · · · · · · · · · · ·

In the Brønsted–Lowry model, a substance that can accept a . Basic solutions have lower activity than water.

Read explanation · OpenStax ↗
Calibration

Establishing the relation between a measured signal and known values or .

Read explanation · Agilent ↗
Cancer

A group of diseases involving abnormal cells that can proliferate without normal restraints and invade tissues.

Read explanation · OpenStax ↗
Carbohydrate

A class of including sugars and their , used for energy storage, structure, and recognition.

Read explanation · OpenStax ↗
Carbonyl group · ·

A carbon double-bonded to oxygen, C=O; present in and many other .

Read explanation · OpenStax ↗
Carboxyl group · ·

An , COOH. In free it is usually to COO⁻ near physiological .

Read explanation · OpenStax ↗
case study

An intensive investigation of one individual, group, or event, often with limited generalizability.

Read explanation · OpenStax ↗
Catalyst · ·

A substance that speeds a by providing a pathway with lower and is regenerated rather than consumed overall.

Read explanation · OpenStax ↗
Chemical reaction ·

A process that rearranges and chemical bonds, converting into .

Read explanation · OpenStax ↗
Chromatin

The complex of and associated , including , in .

Read explanation · OpenStax ↗
Chromosome ·

An organized with associated that carries . A replicated chromosome has two .

Read explanation · OpenStax ↗
Codon

A sequence of three that specifies an or a stop signal.

Read explanation · OpenStax ↗
Concentration

The amount of a substance in a specified volume or mass of mixture.

Read explanation · OpenStax ↗
confirmation bias

Favoring evidence or searches that support an existing belief.

Read explanation · OpenStax ↗
confounder

A variable associated with the exposure and independently related to the outcome, potentially distorting causal interpretation.

Read explanation · OpenStax ↗
convenience sample

A sample selected because its members are readily accessible rather than through a population-based probability scheme.

Read explanation · OpenStax ↗
Covalent bond · ·

A bond in which share pairs. and are covalent.

Read explanation · OpenStax ↗
Cysteine ·

An with a . Two cysteines can form a .

Read explanation · OpenStax ↗
Deoxyribonucleic acid

The that stores genetic information used to specify and sequences.

Read explanation · OpenStax ↗
dependent variable

The measured outcome in a study.

Read explanation · OpenStax ↗
Deprotonation

Removal of a from a or group; this changes its by minus one.

Read explanation · OpenStax ↗
Detergent

An substance that can associate with both water and material; detergents can disrupt or interactions.

Read explanation · Thermo Fisher ↗
Disulfide bond · · ·

A covalent sulfur–sulfur bond formed by of two , which can stabilize structure.

Read explanation · NCBI Bookshelf ↗
DNA replication

Copying so genetic information can be passed to daughter cells. Each guides a complementary new strand.

Read explanation · OpenStax ↗
Electric charge · · ·

An electrical property that can be positive or negative. Opposite charges attract and like charges repel; net charge is the sum of all charges on a particle.

Read explanation · OpenStax ↗
Electron

A negatively subatomic particle. Electron sharing and transfer determine much of chemical bonding.

Read explanation · OpenStax ↗
Endocrine signaling ·

Communication in which enter the circulation and act on distant target cells.

Read explanation · OpenStax ↗
Enzyme

A biological that speeds a without being consumed. Most enzymes are .

Read explanation · OpenStax ↗
ethnicity

Shared cultural history, ancestry, language, or affiliation.

Read explanation · OpenStax ↗
Eukaryote ·

An organism whose cells have a -enclosed ; animals, plants, fungi, and protists are eukaryotes.

Read explanation · OpenStax ↗
FACT complex ·

A -associated complex that helps machinery traverse and supports reorganization.

Read explanation · OpenStax ↗
forebrain

Major developmental brain division including cerebral hemispheres, , and .

Read explanation · OpenStax ↗
Fraction · ·

A portion of a sample collected during a separation, such as the fluid leaving a column during a time interval.

Read explanation · Waters ↗
Functional group

A group of whose chemical behavior gives a characteristic and properties.

Read explanation · OpenStax ↗
Gene

A sequence that contributes to a functional or , together with the information needed to express it.

Read explanation · OpenStax ↗
Gene dosage ·

The number of copies of a or segment; changing dosage can affect expression without altering each copy’s sequence.

Read explanation · NHGRI / NIH ↗
Gene duplication ·

Creation of an additional copy of a or segment, potentially changing or enabling evolutionary divergence.

Read explanation · NHGRI / NIH ↗
Gene expression

Production of a functional from a , including and, for -coding , .

Read explanation · NCBI Bookshelf ↗
Histone

A -associated rich in . Core histones form the around which nucleosomal wraps.

Read explanation · OpenStax ↗
Histone acetyltransferase · ·

An adding acetyl groups to lysines, often promoting accessible and .

Read explanation · OpenStax ↗
Hormone

A chemical messenger released by cells that changes the activity of target cells with matching .

Read explanation · OpenStax ↗
Hydrogen ion · ·

A positively hydrogen species. H⁺ denotes a , which is hydrated in water; its activity determines .

Read explanation · OpenStax ↗
Hydrolysis

Breaking a chemical bond by adding water. hydrolysis separates .

Read explanation · OpenStax ↗
Hydrophilic

Interacting favorably with water, typically because a group is or .

Read explanation · OpenStax ↗
Hydrophobic

Interacting poorly with water. often gather in a ’s interior.

Read explanation · OpenStax ↗
Hydroxide ion ·

The negatively OH⁻. Basic contain a higher hydroxide ion activity than water at the same temperature.

Read explanation · OpenStax ↗
hypothalamus

region coordinating homeostatic, , and autonomic functions.

Read explanation · OpenStax ↗
independent variable

A predictor or manipulated factor whose relation to an outcome is studied.

Read explanation · OpenStax ↗
intelligence quotient

Standardized score comparing cognitive-test performance with a .

Read explanation · OpenStax ↗
Ion · ·

An or with a net because its numbers of and do not balance.

Read explanation · OpenStax ↗
linkage

A tendency of nearby on the same to be inherited together.

Read explanation · OpenStax ↗
Lipid

A broad class of largely or , including fats, , and steroids.

Read explanation · OpenStax ↗
locus

The specific position of a or other feature.

Read explanation · OpenStax ↗
Logarithm · · ·

The exponent needed to obtain a number from a chosen fixed number. For decimal logarithms, log₁₀(100) = 2 because 10² = 100; uses the negative decimal logarithm of activity.

Read explanation · OpenStax ↗
Membrane · · · ·

A thin boundary or sheet. Cell membranes are bilayers containing ; membranes are synthetic supports that hold or for detection.

Read explanation · OpenStax ↗
Messenger RNA ·

An that carries coding information used by to synthesize a .

Read explanation · OpenStax ↗
Molecular chaperone · ·

A that assists other in folding or prevents , without specifying their sequence.

Read explanation · NCBI Bookshelf ↗
Molecule

Two or more joined by . A molecule may be electrically or carry a .

Read explanation · OpenStax ↗
Neutral

Having no net . For a , neutral instead means equal and activities; its is about 7 at 25 °C.

Read explanation · OpenStax ↗
Nitrogenous base · · ·

A nitrogen-containing ring component of ; its pairing interactions help specify sequences.

Read explanation · OpenStax ↗
Nonpolar ·

Lacking a substantial separation of . Nonpolar groups generally interact poorly with water.

Read explanation · OpenStax ↗
Nucleic acid

A of , such as or , used in information storage, expression, and other cellular functions.

Read explanation · OpenStax ↗
Nucleosome

The basic unit of : wrapped around a .

Read explanation · OpenStax ↗
Nucleotide

A joined to a sugar and one or more .

Read explanation · OpenStax ↗
Nucleus ·

A -enclosed compartment containing most of a cell’s .

Read explanation · OpenStax ↗
null hypothesis

A specified population model or parameter claim against which observed data are evaluated.

Read explanation · OpenStax ↗
Octamer

A complex made of eight . A core contains eight .

Read explanation · OpenStax ↗
operational definition

A precise description of how a construct is manipulated or measured in a study.

Read explanation · OpenStax ↗
Oxidation ·

Loss of or an increase in oxidation state. Oxidizing two can form a .

Read explanation · OpenStax ↗
Peptide

A chain of joined by ; the term commonly describes chains shorter than a typical .

Read explanation · OpenStax ↗
Peptide bond ·

A covalent between the carboxyl carbon of one and the amino nitrogen of the next.

Read explanation · OpenStax ↗
pH

A measure of , defined as the negative of activity. Lower pH means greater ; pH influences .

Read explanation · OpenStax ↗
Phosphate group ·

A phosphorus-containing group bonded to oxygens; phosphate groups occur in , , and modified .

Read explanation · OpenStax ↗
Phospholipid

An with a -containing region and tails; a major component of cellular .

Read explanation · OpenStax ↗
Polar

Having an uneven distribution of . Polar groups often interact favorably with water.

Read explanation · OpenStax ↗
Polymer

A large made from many linked molecular building blocks.

Read explanation · OpenStax ↗
Polypeptide

A chain of connected by . A functional can contain one or several such chains.

Read explanation · OpenStax ↗
prejudice

Evaluative toward people based on perceived group membership.

Read explanation · OpenStax ↗
Proline ·

An whose loops back to the nitrogen, restricting rotation and often creating bends.

Read explanation · OpenStax ↗
Protein

One or more folded chains that perform biological roles such as , transport, signaling, or structural support.

Read explanation · OpenStax ↗
Protein aggregation · ·

Association of into larger clusters, often when exposed surfaces of unfolded stick together.

Read explanation · NCBI Bookshelf ↗
Protein backbone ·

The repeating nitrogen–alpha-carbon– chain of a , excluding its variable .

Read explanation · OpenStax ↗
Proton

A positively subatomic particle. In – chemistry, donating a proton means transferring a .

Read explanation · OpenStax ↗
Protonation

Addition of a to an , , or ; this changes its by plus one.

Read explanation · OpenStax ↗
Qualitative analysis

Analysis that identifies a substance or property without necessarily measuring its amount.

Read explanation · Agilent ↗
Quantification · ·

Estimating the amount or of a substance from measured signals and suitable or .

Read explanation · Waters ↗
R group · ·

The variable side chain attached to an ’s . It determines identity, , , and chemical behavior.

Read explanation · OpenStax ↗
random assignment

Allocation of sampled participants or units to conditions by a chance mechanism.

Read explanation · OpenStax ↗
Reactant

A starting substance transformed during a .

Read explanation · OpenStax ↗
Reaction intermediate · ·

A species formed in one step and consumed in another. It occupies a local energy minimum between .

Read explanation · OpenStax ↗
Reaction product ·

A substance formed by a .

Read explanation · OpenStax ↗
Receptor

A that recognizes a particular signal and helps produce a cellular response.

Read explanation · OpenStax ↗
Reduction

Gain of or a decrease in state. Reducing a restores two .

Read explanation · OpenStax ↗
reference group

Group used as a standard for evaluation or comparison.

Read explanation · OpenStax ↗
reliability

Consistency or reproducibility of a measurement under specified conditions.

Read explanation · OpenStax ↗
Ribonucleic acid ·

A with roles in , regulation, and ; carries -coding information.

Read explanation · OpenStax ↗
Ribosome ·

A complex of and that translates into a .

Read explanation · OpenStax ↗
sampling bias

Systematic distortion arising when the selected sample differs from the intended population in relevant ways.

Read explanation · OpenStax ↗
self-esteem

Evaluation of one’s own worth.

Read explanation · OpenStax ↗
Sister chromatid

One of the two copies of a produced by . An intact sister chromatid can supply a template for accurate repair.

Read explanation · Biology LibreTexts / Oregon State University ↗
Solubility ·

The amount of a substance that can dissolve in a under specified conditions. Soluble means able to dissolve; insoluble means only very slightly soluble in that .

Read explanation · OpenStax ↗
Solute

A dissolved component of a .

Read explanation · OpenStax ↗
Solution

A homogeneous mixture in which are dissolved in a .

Read explanation · OpenStax ↗
Solvent

The component of a that dissolves other substances, usually the component present in the greatest amount.

Read explanation · OpenStax ↗
standard deviation

A measure of dispersion around a mean expressed in the original variable’s units.

Read explanation · OpenStax ↗
standard error

The sampling variability of an estimator, often the estimated of sample means.

Read explanation · OpenStax ↗
Subunit ·

An individual chain within a containing multiple chains.

Read explanation · OpenStax ↗
Template strand · · ·

A preexisting strand whose sequence guides complementary nucleic- synthesis.

Read explanation · OpenStax ↗
thalamus

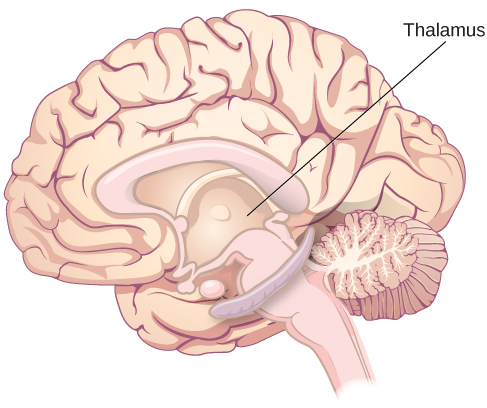
structure containing relays and circuits connecting sensory, motor, and cortical systems.

Read explanation · OpenStax ↗
Thiol group · · · ·

A sulfur bonded to hydrogen, –SH. thiols can form through .

Read explanation · OpenStax ↗
Transcription

Synthesis of using a template.

Read explanation · OpenStax ↗
Transition state

A fleeting, high-energy arrangement at a barrier. It is an energy maximum along the path, rather than a stable .

Read explanation · OpenStax ↗
Translation ·

Synthesis of a on a using the sequence of in .

Read explanation · OpenStax ↗
validity

The extent to which a measure or inference supports its intended interpretation.

Read explanation · OpenStax ↗
withdrawal

Symptoms emerging when exposure to an adapted-to substance is reduced or stopped.

Read explanation · OpenStax ↗

2.2 Approaches to Research

OpenStax · 2.2 Approaches to Research ↗
Instructional page including learning objectives, examples, figures, source tables and questions. Site navigation and embedded media players are omitted; source media links remain available.

Learning Objectives

By the end of this section, you will be able to:

  • Describe the different research methods used by psychologists
  • Discuss the strengths and weaknesses of , naturalistic observation, surveys, and archival research
  • Compare longitudinal and cross-sectional approaches to research
  • Compare and contrast correlation and causation

There are many research methods available to psychologists in their efforts to understand, describe, and explain behavior and the cognitive and biological processes that underlie it. Some methods rely on observational techniques. Other approaches involve interactions between the researcher and the individuals who are being studied—ranging from a series of simple questions to extensive, in-depth interviews—to well-controlled experiments.

Each of these research methods has unique strengths and weaknesses, and each method may only be appropriate for certain types of research questions. For example, studies that rely primarily on observation produce incredible amounts of information, but the ability to apply this information to the larger population is somewhat limited because of small sample sizes. Survey research, on the other hand, allows researchers to easily collect data from relatively large samples. While this allows for results to be generalized to the larger population more easily, the information that can be collected on any given survey is somewhat limited and subject to problems associated with any type of self-reported data. Some researchers conduct archival research by using existing records. While this can be a fairly inexpensive way to collect data that can provide insight into a number of research questions, researchers using this approach have no control on how or what kind of data was collected. All of the methods described thus far are correlational in nature. This means that researchers can speak to important relationships that might exist between two or more variables of interest. However, correlational data cannot be used to make claims about cause-and-effect relationships.

Correlational research can find a relationship between two variables, but the only way a researcher can claim that the relationship between the variables is cause and effect is to perform an experiment. In experimental research, which will be discussed later in this chapter, there is a tremendous amount of control over variables of interest. While this is a powerful approach, experiments are often conducted in artificial settings. This calls into question the of experimental findings with regard to how they would apply in real-world settings. In addition, many of the questions that psychologists would like to answer cannot be pursued through experimental research because of ethical concerns.

Clinical or

In 2011, the New York Times published a feature story on Krista and Tatiana Hogan, Canadian twin girls. These particular twins are unique because Krista and Tatiana are conjoined twins, connected at the head. There is evidence that the two girls are connected in a part of the brain called the , which is a major sensory relay center. Most incoming sensory information is sent through the before reaching higher regions of the cerebral cortex for processing.

Link to Learning

The implications of this potential connection mean that it might be possible for one twin to experience the sensations of the other twin. For instance, if Krista is watching a particularly funny television program, Tatiana might smile or laugh even if she is not watching the program. This particular possibility has piqued the interest of many neuroscientists who seek to understand how the brain uses sensory information.

These twins represent an enormous resource in the study of the brain, and since their condition is very rare, it is likely that as long as their family agrees, scientists will follow these girls very closely throughout their lives to gain as much information as possible (Dominus, 2011).

Over time, it has become clear that while Krista and Tatiana share some sensory experiences and motor control, they remain two distinct individuals, which provides invaluable insight for researchers interested in the mind and the brain (Egnor, 2017).

In observational research, scientists are conducting a clinical or when they focus on one person or just a few individuals. Indeed, some scientists spend their entire careers studying just 10–20 individuals. Why would they do this? Obviously, when they focus their attention on a very small number of people, they can gain a precious amount of insight into those cases. The richness of information that is collected in clinical or is unmatched by any other single research method. This allows the researcher to have a very deep understanding of the individuals and the particular phenomenon being studied.

If clinical or provide so much information, why are they not more frequent among researchers? As it turns out, the major benefit of this particular approach is also a weakness. As mentioned earlier, this approach is often used when studying individuals who are interesting to researchers because they have a rare characteristic. Therefore, the individuals who serve as the focus of are not like most other people. If scientists ultimately want to explain all behavior, focusing attention on such a special group of people can make it difficult to generalize any observations to the larger population as a whole. Generalizing refers to the ability to apply the findings of a particular research project to larger segments of society. Again, provide enormous amounts of information, but since the cases are so specific, the potential to apply what’s learned to the average person may be very limited.

Naturalistic Observation

If you want to understand how behavior occurs, one of the best ways to gain information is to simply observe the behavior in its natural context. However, people might change their behavior in unexpected ways if they know they are being observed. How do researchers obtain accurate information when people tend to hide their natural behavior? As an example, imagine that your professor asks everyone in your class to raise their hand if they always wash their hands after using the restroom. Chances are that almost everyone in the classroom will raise their hand, but do you think hand washing after every trip to the restroom is really that universal?

This is very similar to the phenomenon mentioned earlier in this chapter: many individuals do not feel comfortable answering a question honestly. But if we are committed to finding out the facts about hand washing, we have other options available to us.

Suppose we send a classmate into the restroom to actually watch whether everyone washes their hands after using the restroom. Will our observer blend into the restroom environment by wearing a white lab coat, sitting with a clipboard, and staring at the sinks? We want our researcher to be inconspicuous—perhaps standing at one of the sinks pretending to put in contact lenses while secretly recording the relevant information. This type of observational study is called naturalistic observation: observing behavior in its natural setting. To better understand peer exclusion, Suzanne Fanger collaborated with colleagues at the University of Texas to observe the behavior of preschool children on a playground. How did the observers remain inconspicuous over the duration of the study? They equipped a few of the children with wireless microphones (which the children quickly forgot about) and observed while taking notes from a distance. Also, the children in that particular preschool (a “laboratory preschool”) were accustomed to having observers on the playground (Fanger, Frankel, & Hazen, 2012).

It is critical that the observer be as unobtrusive and as inconspicuous as possible: when people know they are being watched, they are less likely to behave naturally. If you have any doubt about this, ask yourself how your driving behavior might differ in two situations: In the first situation, you are driving down a deserted highway during the middle of the day; in the second situation, you are being followed by a police car down the same deserted highway (Figure 2.7).

A photograph shows two police cars driving, one with its lights flashing.
Figure 2.7 — 2.2 Approaches to Research

Figure 2.7 Seeing a police car behind you would probably affect your driving behavior. (credit: Michael Gil)

Rose M. Spielman, William J. Jenkins, and Marilyn D. Lovett, Psychology 2E, OpenStax. (credit: Michael Gil) · CC BY-NC-SA 4.0 · Original image ↗ · Access for free ↗

It should be pointed out that naturalistic observation is not limited to research involving humans. Indeed, some of the best-known examples of naturalistic observation involve researchers going into the field to observe various kinds of animals in their own environments. As with human studies, the researchers maintain their distance and avoid interfering with the animal subjects so as not to influence their natural behaviors. Scientists have used this technique to study social hierarchies and interactions among animals ranging from ground squirrels to gorillas. The information provided by these studies is invaluable in understanding how those animals organize socially and communicate with one another. The anthropologist Jane Goodall, for example, spent nearly five decades observing the behavior of chimpanzees in Africa (Figure 2.8). As an illustration of the types of concerns that a researcher might encounter in naturalistic observation, some scientists criticized Goodall for giving the chimps names instead of referring to them by numbers—using names was thought to undermine the emotional detachment required for the objectivity of the study (McKie, 2010).

(a) A photograph shows Jane Goodall speaking from a lectern. (b) A photograph shows a chimpanzee’s face.
Figure 2.8 — 2.2 Approaches to Research

Figure 2.8 (a) Jane Goodall made a career of conducting naturalistic observations of (b) chimpanzee behavior. (credit “Jane Goodall”: modification of work by Erik Hersman; “chimpanzee”: modification of work by “Afrika Force”/Flickr.com)

Rose M. Spielman, William J. Jenkins, and Marilyn D. Lovett, Psychology 2E, OpenStax. (credit “Jane Goodall”: modification of work by Erik Hersman; “chimpanzee”: modification of work by “Afrika Force”/Flickr.com) · CC BY-NC-SA 4.0 · Original image ↗ · Access for free ↗

The greatest benefit of naturalistic observation is the , or accuracy, of information collected unobtrusively in a natural setting. Having individuals behave as they normally would in a given situation means that we have a higher degree of ecological , or realism, than we might achieve with other research approaches. Therefore, our ability to generalize the findings of the research to real-world situations is enhanced. If done correctly, we need not worry about people or animals modifying their behavior simply because they are being observed. Sometimes, people may assume that reality programs give us a glimpse into authentic human behavior. However, the principle of inconspicuous observation is violated as reality stars are followed by camera crews and are interviewed on camera for personal confessionals. Given that environment, we must doubt how natural and realistic their behaviors are.

The major downside of naturalistic observation is that they are often difficult to set up and control. In our restroom study, what if you stood in the restroom all day prepared to record people’s hand washing behavior and no one came in? Or, what if you have been closely observing a troop of gorillas for weeks only to find that they migrated to a new place while you were sleeping in your tent? The benefit of realistic data comes at a cost. As a researcher you have no control of when (or if) you have behavior to observe. In addition, this type of observational research often requires significant investments of time, money, and a good dose of luck.

Sometimes studies involve structured observation. In these cases, people are observed while engaging in set, specific tasks. An excellent example of structured observation comes from Strange Situation by Mary Ainsworth (you will read more about this in the chapter on lifespan development). The Strange Situation is a procedure used to evaluate styles that exist between an infant and caregiver. In this scenario, caregivers bring their infants into a room filled with toys. The Strange Situation involves a number of phases, including a stranger coming into the room, the caregiver leaving the room, and the caregiver’s return to the room. The infant’s behavior is closely monitored at each phase, but it is the behavior of the infant upon being reunited with the caregiver that is most telling in terms of characterizing the infant’s style with the caregiver.

Another potential problem in observational research is observer bias. Generally, people who act as observers are closely involved in the research project and may unconsciously skew their observations to fit their research goals or expectations. To protect against this type of bias, researchers should have clear criteria established for the types of behaviors recorded and how those behaviors should be classified. In addition, researchers often compare observations of the same event by multiple observers, in order to test inter-rater : a measure of that assesses the consistency of observations by different observers.

Surveys

Often, psychologists develop surveys as a means of gathering data. Surveys are lists of questions to be answered by research participants, and can be delivered as paper-and-pencil questionnaires, administered electronically, or conducted verbally (Figure 2.9). Generally, the survey itself can be completed in a short time, and the ease of administering a survey makes it easy to collect data from a large number of people.

Surveys allow researchers to gather data from larger samples than may be afforded by other research methods. A sample is a subset of individuals selected from a population, which is the overall group of individuals that the researchers are interested in. Researchers study the sample and seek to generalize their findings to the population. Generally, researchers will begin this process by calculating various measures of central tendency from the data they have collected. These measures provide an overall summary of what a typical response looks like. There are three measures of central tendency: mode, median, and mean. The mode is the most frequently occurring response, the median lies at the middle of a given data set, and the mean is the arithmetic average of all data points. Means tend to be most useful in conducting additional analyses like those described below; however, means are very sensitive to the effects of outliers, and so one must be aware of those effects when making assessments of what measures of central tendency tell us about a data set in question.

A sample online survey reads, “Dear visitor, your opinion is important to us. We would like to invite you to participate in a short survey to gather your opinions and feedback on your news consumption habits. The survey will take approximately 10-15 minutes. Simply click the “Yes” button below to launch the survey. Would you like to participate?” Two buttons are labeled “yes” and “no.”
Figure 2.9 — 2.2 Approaches to Research

Figure 2.9 Surveys can be administered in a number of ways, including electronically administered research, like the survey shown here. (credit: Robert Nyman)

Rose M. Spielman, William J. Jenkins, and Marilyn D. Lovett, Psychology 2E, OpenStax. (credit: Robert Nyman) · CC BY-NC-SA 4.0 · Original image ↗ · Access for free ↗

There is both strength and weakness of the survey in comparison to . By using surveys, we can collect information from a larger sample of people. A larger sample is better able to reflect the actual diversity of the population, thus allowing better generalizability. Therefore, if our sample is sufficiently large and diverse, we can assume that the data we collect from the survey can be generalized to the larger population with more certainty than the information collected through a . However, given the greater number of people involved, we are not able to collect the same depth of information on each person that would be collected in a .

Another potential weakness of surveys is something we touched on earlier in this chapter: People don't always give accurate responses. They may lie, misremember, or answer questions in a way that they think makes them look good. For example, people may report drinking less alcohol than is actually the case.

Any number of research questions can be answered through the use of surveys. One real-world example is the research conducted by Jenkins, Ruppel, Kizer, Yehl, and Griffin (2012) about the backlash against the US Arab-American community following the terrorist attacks of September 11, 2001. Jenkins and colleagues wanted to determine to what extent these negative attitudes toward Arab-Americans still existed nearly a decade after the attacks occurred. In one study, 140 research participants filled out a survey with 10 questions, including questions asking directly about the participant’s overt prejudicial attitudes toward people of various ethnicities. The survey also asked indirect questions about how likely the participant would be to interact with a person of a given in a variety of settings (such as, “How likely do you think it is that you would introduce yourself to a person of Arab-American descent?”). The results of the research suggested that participants were unwilling to report prejudicial attitudes toward any ethnic group. However, there were significant differences between their pattern of responses to questions about social interaction with Arab-Americans compared to other ethnic groups: they indicated less willingness for social interaction with Arab-Americans compared to the other ethnic groups. This suggested that the participants harbored subtle forms of against Arab-Americans, despite their assertions that this was not the case (Jenkins et al., 2012).

Archival Research

Some researchers gain access to large amounts of data without interacting with a single research participant. Instead, they use existing records to answer various research questions. This type of research approach is known as archival research. Archival research relies on looking at past records or data sets to look for interesting patterns or relationships.

For example, a researcher might access the academic records of all individuals who enrolled in college within the past ten years and calculate how long it took them to complete their degrees, as well as course loads, grades, and extracurricular involvement. Archival research could provide important information about who is most likely to complete their education, and it could help identify important risk factors for struggling students (Figure 2.10).

(a) A photograph shows stacks of paper files on shelves. (b) A photograph shows a computer.
Figure 2.10 — 2.2 Approaches to Research

Figure 2.10 A researcher doing archival research examines records, whether archived as a (a) hardcopy or (b) electronically. (credit “paper files”: modification of work by “Newtown graffiti”/Flickr; “computer”: modification of work by INPIVIC Family/Flickr)

Rose M. Spielman, William J. Jenkins, and Marilyn D. Lovett, Psychology 2E, OpenStax. (credit “paper files”: modification of work by “Newtown graffiti”/Flickr; “computer”: modification of work by INPIVIC Family/Flickr) · CC BY-NC-SA 4.0 · Original image ↗ · Access for free ↗

In comparing archival research to other research methods, there are several important distinctions. For one, the researcher employing archival research never directly interacts with research participants. Therefore, the investment of time and money to collect data is considerably less with archival research. Additionally, researchers have no control over what information was originally collected. Therefore, research questions have to be tailored so they can be answered within the structure of the existing data sets. There is also no guarantee of consistency between the records from one source to another, which might make comparing and contrasting different data sets problematic.

Longitudinal and Cross-Sectional Research

Sometimes we want to see how people change over time, as in studies of human development and lifespan. When we test the same group of individuals repeatedly over an extended period of time, we are conducting longitudinal research. Longitudinal research is a research design in which data-gathering is administered repeatedly over an extended period of time. For example, we may survey a group of individuals about their dietary habits at age 20, retest them a decade later at age 30, and then again at age 40.

Another approach is cross-sectional research. In cross-sectional research, a researcher compares multiple segments of the population at the same time. Using the dietary habits example above, the researcher might directly compare different groups of people by age. Instead of studying a group of people for 20 years to see how their dietary habits changed from decade to decade, the researcher would study a group of 20-year-old individuals and compare them to a group of 30-year-old individuals and a group of 40-year-old individuals. While cross-sectional research requires a shorter-term investment, it is also limited by differences that exist between the different generations (or cohorts) that have nothing to do with age per , but rather reflect the social and cultural experiences of different generations of individuals that make them different from one another.

To illustrate this concept, consider the following survey findings. In recent years there has been significant growth in the popular support of same-sex marriage. Many studies on this topic break down survey participants into different age groups. In general, younger people are more supportive of same-sex marriage than are those who are older (Jones, 2013). Does this mean that as we age we become less open to the idea of same-sex marriage, or does this mean that older individuals have different perspectives because of the social climates in which they grew up? Longitudinal research is a powerful approach because the same individuals are involved in the research project over time, which means that the researchers need to be less concerned with differences among cohorts affecting the results of their study.

Often longitudinal studies are employed when researching various diseases in an effort to understand particular risk factors. Such studies often involve tens of thousands of individuals who are followed for several decades. Given the enormous number of people involved in these studies, researchers can feel confident that their findings can be generalized to the larger population. The Prevention Study-3 (CPS-3) is one of a series of longitudinal studies sponsored by the American Society aimed at determining predictive risk factors associated with . When participants enter the study, they complete a survey about their lives and family histories, providing information on factors that might cause or prevent the development of . Then every few years the participants receive additional surveys to complete. In the end, hundreds of thousands of participants will be tracked over 20 years to determine which of them develop and which do not.

Clearly, this type of research is important and potentially very informative. For instance, earlier longitudinal studies sponsored by the American Society provided some of the first scientific demonstrations of the now well-established links between increased rates of and smoking (American Society, n.d.) (Figure 2.11).

A photograph shows pack of cigarettes and cigarettes in an ashtray. The pack of cigarettes reads, “Surgeon general’s warning: smoking causes lung cancer, heart disease, emphysema, and may complicate pregnancy.”
Figure 2.11 — 2.2 Approaches to Research

Figure 2.11 Longitudinal research like the CPS-3 help us to better understand how smoking is associated with cancer and other diseases. (credit: CDC/Debora Cartagena)

Rose M. Spielman, William J. Jenkins, and Marilyn D. Lovett, Psychology 2E, OpenStax. (credit: CDC/Debora Cartagena) · CC BY-NC-SA 4.0 · Original image ↗ · Access for free ↗

As with any research strategy, longitudinal research is not without limitations. For one, these studies require an incredible time investment by the researcher and research participants. Given that some longitudinal studies take years, if not decades, to complete, the results will not be known for a considerable period of time. In addition to the time demands, these studies also require a substantial financial investment. Many researchers are unable to commit the resources necessary to see a longitudinal project through to the end.

Research participants must also be willing to continue their participation for an extended period of time, and this can be problematic. People move, get married and take new names, get ill, and eventually die. Even without significant life changes, some people may simply choose to discontinue their participation in the project. As a result, the rates, or in the number of research participants due to dropouts, in longitudinal studies are quite high and increase over the course of a project. For this reason, researchers using this approach typically recruit many participants fully expecting that a substantial number will drop out before the end. As the study progresses, they continually check whether the sample still represents the larger population, and make adjustments as necessary.

1.2 Data, Sampling, and Variation in Data and Sampling

OpenStax · 1.2 Data, Sampling, and Variation in Data and Sampling ↗
Instructional page including learning objectives, examples, figures, source tables and questions. Site navigation and embedded media players are omitted; source media links remain available.

Data may come from a population or from a sample. Lowercase letters like x or y generally are used to represent data values. Most data can be put into the following categories:

data are the result of categorizing or describing attributes of a population. data are also often called categorical data. Hair color, blood type, ethnic group, the car a person drives, and the street a person lives on are examples of data. data are generally described by words or letters. For instance, hair color might be black, dark brown, light brown, blonde, gray, or red. Blood type might be AB+, O-, or B+. Researchers often prefer to use data over data because it lends itself more easily to mathematical analysis. For example, it does not make sense to find an average hair color or blood type.

data are always numbers. data are the result of counting or measuring attributes of a population. Amount of money, pulse rate, weight, number of people living in your town, and number of students who take statistics are examples of data. data may be either discrete or continuous.

All data that are the result of counting are called discrete data. These data take on only certain numerical values. If you count the number of phone calls you receive for each day of the week, you might get values such as zero, one, two, or three.

Data that are not only made up of counting numbers, but that may include , decimals, or irrational numbers, are called continuous data. Continuous data are often the results of measurements like lengths, weights, or times. A list of the lengths in minutes for all the phone calls that you make in a week, with numbers like 2.4, 7.5, or 11.0, would be continuous data.

Example 1.5

Data Sample of Discrete Data

The data are the number of books students carry in their backpacks. You sample five students. Two students carry three books, one student carries four books, one student carries two books, and one student carries one book. The numbers of books (three, four, two, and one) are the discrete data.

Try It 1.5

The data are the number of machines in a gym. You sample five gyms. One gym has 12 machines, one gym has 15 machines, one gym has ten machines, one gym has 22 machines, and the other gym has 20 machines. What type of data is this?

Example 1.6

Data Sample of Continuous Data

The data are the weights of backpacks with books in them. You sample the same five students. The weights (in pounds) of their backpacks are 6.2, 7, 6.8, 9.1, 4.3. Notice that backpacks carrying three books can have different weights. Weights are continuous data.

Try It 1.6

The data are the areas of lawns in square feet. You sample five houses. The areas of the lawns are 144 sq. feet, 160 sq. feet, 190 sq. feet, 180 sq. feet, and 210 sq. feet. What type of data is this?

Example 1.7

You go to the supermarket and purchase three cans of soup (19 ounces tomato bisque, 14.1 ounces lentil, and 19 ounces Italian wedding), two packages of nuts (walnuts and peanuts), four different kinds of vegetable (broccoli, cauliflower, spinach, and carrots), and two desserts (16 ounces pistachio ice cream and 32 ounces chocolate chip cookies).

Problem

Name data sets that are discrete, continuous, and .

One Possible :

  • The three cans of soup, two packages of nuts, four kinds of vegetables and two desserts are discrete data because you count them.
  • The weights of the soups (19 ounces, 14.1 ounces, 19 ounces) are continuous data because you measure weights as precisely as possible.
  • Types of soups, nuts, vegetables and desserts are data because they are categorical.

Try to identify additional data sets in this example.

Try It 1.7

The following list of materials was purchased by a purchase manager in a company:

  • Two types of nails (2 kg box nails, 3 kg roofing nails)
  • One type of oil (4 L machine oil)
  • Four types of screws (3 kg wood screws, 5 kg machine screws, 1 kg set screws, 2 kg socket screws)

Name data sets that are discrete, continuous, and .

Example 1.8

The data are the colors of backpacks. Again, you sample the same five students. One student has a red backpack, two students have black backpacks, one student has a green backpack, and one student has a gray backpack. The colors red, black, black, green, and gray are data.

Try It 1.8

The data are the colors of houses. You sample five houses. The colors of the houses are white, yellow, white, red, and white. What type of data is this?

NOTE

You may collect data as numbers and report it categorically. For example, the quiz scores for each student are recorded throughout the term. At the end of the term, the quiz scores are reported as A, B, C, D, or F.

Example 1.9

Problem

Work collaboratively to determine the correct data type ( or ). Indicate whether data are continuous or discrete. Hint: Data that are discrete often start with the words "the number of."

  1. the number of pairs of shoes you own
  2. the type of car you drive
  3. the distance it is from your home to the nearest grocery store
  4. the number of classes you take per school year.
  5. the type of calculator you use
  6. weights of dogs at an animal shelter
  7. number of correct answers on a quiz
  8. scores (This may cause some discussion.)

Items a, d, and g are discrete; items c, f, and h are continuous; items b and e are , or categorical.

Try It 1.9

Determine the correct data type ( or ) for the number of cars in a parking lot. Indicate whether data are continuous or discrete.

Example 1.10

Problem

A statistics professor collects information about the classification of her students as first-year students, sophomores, juniors, or seniors. The data she collects are summarized in the pie chart Figure 1.3. What type of data does this graph show?

This is a pie chart showing the class classification of statistics students. The chart has 4 sections labeled Freshman, Sophomore, Junior, Senior. A question is asked below the pie chart: what type of data does this graph show?
Figure 1.3 — 1.2 Data, Sampling, and Variation in Data and Sampling

Figure 1.3

Barbara Illowsky and Susan Dean, Introductory Statistics 2E, OpenStax. · CC BY-NC-SA 4.0 · Original image ↗ · Access for free ↗

This pie chart shows the students in each year, which is (or categorical) data.

Try It 1.10

The registrar at State University keeps records of the number of credit hours students complete each semester. The data collected are summarized in the histogram. The class boundaries are 10 to less than 13, 13 to less than 16, 16 to less than 19, 19 to less than 22, and 22 to less than 25.

This histogram consists of 5 bars with the x-axis marked at intervals of 3 from 10 to 25, and the y-axis in increments of 100 from 0 to 800. The height of bars shows the number of students in each interval. Interval 10 to 13 is at 250, interval 13 to 16 is at 580, interval 16 to 19 is at 720, interval 19 to 22 is at 620, and interval 22 to 25 is at 250.
Figure 1.4 — 1.2 Data, Sampling, and Variation in Data and Sampling

Figure 1.4

Barbara Illowsky and Susan Dean, Introductory Statistics 2E, OpenStax. · CC BY-NC-SA 4.0 · Original image ↗ · Access for free ↗


What type of data does this graph show?

Data Discussion

Below are tables comparing the number of part-time and full-time students at De Anza College and Foothill College enrolled for the most recent spring quarter. The tables display counts (frequencies) and percentages or proportions (relative frequencies). The percent columns make comparing the same categories in the colleges easier. Displaying percentages along with the numbers is often helpful, but it is particularly important when comparing sets of data that do not have the same totals, such as the total enrollments for both colleges in this example. Notice how much larger the percentage for part-time students at Foothill College is compared to De Anza College.

De Anza College Foothill College
Number Percent Number Percent
Full-time 9,200 40.9% Full-time 4,059 28.6%
Part-time 13,296 59.1% Part-time 10,124 71.4%
Total 22,496 100% Total 14,183 100%
Table 1.3 Most Recent Spring Quarter

Tables are a good way of organizing and displaying data. But graphs can be even more helpful in understanding the data. There are no strict rules concerning which graphs to use. Two graphs that are used to display data are pie charts and bar graphs.

In a pie chart, categories of data are represented by wedges in a circle and are proportional in size to the percent of individuals in each category.

In a bar graph, the length of the bar for each category is proportional to the number or percent of individuals in each category. Bars may be vertical or horizontal.

A Pareto chart consists of bars that are sorted into order by category size (largest to smallest).

Look at Figure 1.5 and Figure 1.6 and determine which graph (pie or bar) you think displays the comparisons better.

It is a good idea to look at a variety of graphs to see which is the most helpful in displaying the data. We might make different choices of what we think is the “best” graph depending on the data and the context. Our choice also depends on what we are using the data for.

Side-by-side pie charts showing the distribution of part time and full time students. The chart on the left is titled De Anza college. It is divided into two sections showing that part time students represent 59.1% of the population and full time students make up 40.9%. The chart on the right is titled Foothill college. It is divided into two sections showing that part time students represent 71.4% of the population and full time students make up 28.6%.
Figure 1.5 — 1.2 Data, Sampling, and Variation in Data and Sampling

Figure 1.5

Barbara Illowsky and Susan Dean, Introductory Statistics 2E, OpenStax. · CC BY-NC-SA 4.0 · Original image ↗ · Access for free ↗
A bar chart titled 'Student Status' shows student numbers for De Anza and Foothill colleges. De Anza has 9,200 full-time and 13,296 part-time students. Foothill has 4,059 full-time and 10,124 part-time students.
Figure 1.6 — 1.2 Data, Sampling, and Variation in Data and Sampling

Figure 1.6

Barbara Illowsky and Susan Dean, Introductory Statistics 2E, OpenStax. · CC BY-NC-SA 4.0 · Original image ↗ · Access for free ↗

Percentages That Add to More (or Less) Than 100%

Sometimes percentages add up to be more than 100% (or less than 100%). In the graph, the percentages add to more than 100% because students can be in more than one category. A bar graph is appropriate to compare the relative size of the categories. A pie chart cannot be used. It also could not be used if the percentages added to less than 100%.

Characteristic/Category Percent
Full-Time Students 40.9%
Students who intend to transfer to a 4-year educational institution 48.6%
Students under age 25 61.0%
TOTAL 150.5%
Table 1.4 De Anza College Most Recent Spring Quarter
A bar graph. The vertical axis marks values from 0% to 100% in intervals of 20%. The horizontal axis categories are Under age 25 (height of bar shows 61.0%), Intend to transfer (height of bar shows 48.6%), Full-time (height of bar shows 40.9%), and All students (height of bar shows 100%).
Figure 1.7 — 1.2 Data, Sampling, and Variation in Data and Sampling

Figure 1.7

Barbara Illowsky and Susan Dean, Introductory Statistics 2E, OpenStax. · CC BY-NC-SA 4.0 · Original image ↗ · Access for free ↗

Omitting Categories/Missing Data

The table displays of Students but is missing the "Other/Unknown" category. This category contains people who did not feel they fit into any of the categories or declined to respond. Notice that the frequencies do not add up to the total number of students. In this situation, create a bar graph and not a pie chart.

Frequency Percent
Asian 8,794 36.1%
Black 1,412 5.8%
Filipino 1,298 5.3%
Hispanic/Latino 4,180 17.1%
Native American 146 0.6%
Pacific Islander 236 1.0%
White 5,978 24.5%
TOTAL 22,044 out of 24,382 90.4% out of 100%
Table 1.5 of Students at De Anza College in the Most Recent Fall Term
A bar graph showing ethnicity of students. The vertical axis marks values from 0.0% to 40.0% in intervals of 5.0%. The horizontal axis categories are Asian (height of bar shows 36.1%), Black (height of bar shows 5.8%), Filipino (height of bar shows 5.3%), Hispanic/Latino (height of bar shows 17.1%), Native American (height of bar shows 0.6%), Pacific Islander (height of bar shows 1.0%),and White (height of bar shows 24.5%).
Figure 1.8 — 1.2 Data, Sampling, and Variation in Data and Sampling

Figure 1.8

Barbara Illowsky and Susan Dean, Introductory Statistics 2E, OpenStax. · CC BY-NC-SA 4.0 · Original image ↗ · Access for free ↗

The following graph is the same as the previous graph but the “Other/Unknown” percent (9.6%) has been included. The “Other/Unknown” category is large compared to some of the other categories (Native American, 0.6%, Pacific Islander 1.0%). This is important to know when we think about what the data are telling us.

This particular bar graph in Figure 1.9 can be difficult to understand visually. The graph in Figure 1.10 is a Pareto chart. The Pareto chart has the bars sorted from largest to smallest and is easier to read and interpret.

Bar graph consisting of 8 bars with values matching the given data. Horizontal axis has all ethinicity of student. Vertical axis ranges ffrom 0 to 40 percent in increments of 5 percent.
Figure 1.9 — 1.2 Data, Sampling, and Variation in Data and Sampling

Figure 1.9 Bar Graph with Other/Unknown Category

Barbara Illowsky and Susan Dean, Introductory Statistics 2E, OpenStax. · CC BY-NC-SA 4.0 · Original image ↗ · Access for free ↗
A Pareto chart is a bar graph with the bars ordered from greatest height to least. This one shows ethnicity of students. The vertical axis marks values from 0.0% to 40.0% in intervals of 5.0%. The horizontal axis categories are Asian (height of bar shows 36.1%), White (height of bar shows 24.5%), Hispanic/Latino (height of bar shows 17.1%), Other/Unknown (height of bar shows 9.6%), Black (height of bar shows 5.8%), Filipino (height of bar shows 5.3%), Pacific Islander (height of bar shows 1.0%), and Native American (height of bar shows 0.6%).
Figure 1.10 — 1.2 Data, Sampling, and Variation in Data and Sampling

Figure 1.10 Pareto Chart With Bars Sorted by Size

Barbara Illowsky and Susan Dean, Introductory Statistics 2E, OpenStax. · CC BY-NC-SA 4.0 · Original image ↗ · Access for free ↗

Pie Charts: No Missing Data

The following pie charts have the “Other/Unknown” category included (since the percentages must add to 100%). The chart in Figure 1.11(b) is organized by the size of each wedge, which makes it a more visually informative graph than the unsorted, alphabetical graph in Figure 1.11(a).

Two pie charts are titled Ethnicity of Students. Chart (a) The sections of the chart are ordered alphabetically. Clockwise from the top, the sections show that Asian students make up 36.1% of students, Black 5.8%, Filipino 5.3%, Hispanic/Latino 17.1%, Native American 0.6%, Pacific Islander 1.0%, White 24.5%, and Other 9.6%. Chart (b) This is the same data as shown in chart (a), but the sections of the chart are now ordered from greatest area to least. Clockwise from the top, the sections show that Asian students make up 36.1% of students, White 24.5%, Hispanic/Latino 17.1%, Other 9.6%, Black 5.8%, Filipino 5.3%, Pacific Islander 1.0%, and Native American 0.6%.
Figure 1.11 — 1.2 Data, Sampling, and Variation in Data and Sampling

Figure 1.11

Barbara Illowsky and Susan Dean, Introductory Statistics 2E, OpenStax. · CC BY-NC-SA 4.0 · Original image ↗ · Access for free ↗

Sampling

Gathering information about an entire population often costs too much or is virtually impossible. Instead, we use a sample of the population. A sample should have the same characteristics as the population it is representing. Most statisticians use various methods of random sampling in an attempt to achieve this goal. This section will describe a few of the most common methods. There are several different methods of random sampling. In each form of random sampling, each member of a population initially has an equal chance of being selected for the sample. Each method has pros and cons. The easiest method to describe is called a simple random sample. Any group of n individuals is equally likely to be chosen as any other group of n individuals if the simple random sampling technique is used. In other words, each sample of the same size has an equal chance of being selected. For example, suppose Lisa wants to form a four-person study group (herself and three other people) from her pre-calculus class, which has 31 members not including Lisa. To choose a simple random sample of size three from the other members of her class, Lisa could put all 31 names in a , shake the , close her eyes, and pick out three names. A more technological way is for Lisa to first list the last names of the members of her class together with a two-digit number, as in Table 1.6:

ID Name ID Name ID Name
00 Anselmo 11 King 21 Roquero
01 Bautista 12 Legeny 22 Roth
02 Bayani 13 Lundquist 23 Rowell
03 Cheng 14 Macierz 24 Salangsang
04 Cuarismo 15 Motogawa 25 Slade
05 Cuningham 16 Okimoto 26 Stratcher
06 Fontecha 17 Patel 27 Tallai
07 Hong 18 Price 28 Tran
08 Hoobler 19 Quizon 29 Wai
09 Jiao 20 Reyes 30 Wood
10 Khan
Table 1.6 Class Roster

Lisa can use a table of random numbers (found in many statistics books and mathematical handbooks), a calculator, or a computer to generate random numbers. For this example, suppose Lisa chooses to generate random numbers from a calculator. The numbers generated are as follows:

0.94360; 0.99832; 0.14669; 0.51470; 0.40581; 0.73381; 0.04399

Lisa reads two-digit groups until she has chosen three class members (that is, she reads 0.94360 as the groups 94, 43, 36, 60). Each random number may only contribute one class member. If she needed to, Lisa could have generated more random numbers.

The random numbers 0.94360 and 0.99832 do not contain appropriate two digit numbers. However the third random number, 0.14669, contains 14 (the fourth random number also contains 14), the fifth random number contains 05, and the seventh random number contains 04. The two-digit number 14 corresponds to Macierz, 05 corresponds to Cuningham, and 04 corresponds to Cuarismo. Besides herself, Lisa’s group will consist of Marcierz, Cuningham, and Cuarismo.

Using the TI-83, 83+, 84, 84+ Calculator

To generate random numbers:

  • Press MATH.
  • Arrow over to PRB.
  • Press 5:randInt(. Enter 0, 30).
  • Press ENTER for the first random number.
  • Press ENTER two more times for the other 2 random numbers. If there is a repeat press ENTER again.

Note: randInt(0, 30, 3) will generate 3 random numbers.

A calculator screen shows the following set on separate lines: randInt (0, 30); 29; randInt (0, 30); 28; randInt (0, 30); 4.
Figure 1.12 — 1.2 Data, Sampling, and Variation in Data and Sampling

Figure 1.12

Barbara Illowsky and Susan Dean, Introductory Statistics 2E, OpenStax. · CC BY-NC-SA 4.0 · Original image ↗ · Access for free ↗

Besides simple random sampling, there are other forms of sampling that involve a chance process for getting the sample. Other well-known random sampling methods are the stratified sample, the cluster sample, and the systematic sample.

To choose a stratified sample, divide the population into groups called strata and then take a proportionate number from each stratum. For example, you could stratify (group) your college population by department and then choose a proportionate simple random sample from each stratum (each department) to get a stratified random sample. To choose a simple random sample from each department, number each member of the first department, number each member of the second department, and do the same for the remaining departments. Then use simple random sampling to choose proportionate numbers from the first department and do the same for each of the remaining departments. Those numbers picked from the first department, picked from the second department, and so on represent the members who make up the stratified sample.

To choose a cluster sample, divide the population into clusters (groups) and then randomly select some of the clusters. All the members from these clusters are in the cluster sample. For example, if you randomly sample four departments from your college population, the four departments make up the cluster sample. Divide your college faculty by department. The departments are the clusters. Number each department, and then choose four different numbers using simple random sampling. All members of the four departments with those numbers are the cluster sample.

To choose a systematic sample, randomly select a starting point and take every nth piece of data from a listing of the population. For example, suppose you have to do a phone survey. Your phone book contains 20,000 residence listings. You must choose 400 names for the sample. Number the population 1–20,000 and then use a simple random sample to pick a number that represents the first name in the sample. Then choose every fiftieth name thereafter until you have a total of 400 names (you might have to go back to the beginning of your phone list). Systematic sampling is frequently chosen because it is a simple method.

A type of sampling that is non-random is . involves using results that are readily available. For example, a computer software store conducts a marketing study by interviewing potential customers who happen to be in the store browsing through the available software. The results of may be very good in some cases and highly biased (favor certain outcomes) in others.

Sampling data should be done very carefully. Collecting data carelessly can have devastating results. Surveys mailed to households and then returned may be very biased (they may favor a certain group). It is better for the person conducting the survey to select the sample respondents.

Sampling with replacement is truly random sampling. That is, once a member is picked, that member goes back into the population and thus may be chosen more than once. However for practical reasons, in most populations, simple random sampling without replacement is done. Surveys are typically done without replacement. That is, a member of the population may be chosen only once. Most samples are taken from large populations and the sample tends to be small in comparison to the population. Since this is the case, sampling without replacement is approximately the same as sampling with replacement because the chance of picking the same individual more than once with replacement is very low.

Sampling without replacement instead of sampling with replacement becomes a mathematical issue only when the population is small.

When you analyze data, it is important to be aware of sampling errors and nonsampling errors. The actual process of sampling causes sampling errors. For example, the sample may not be large enough. Factors not related to the sampling process cause nonsampling errors. A defective counting device can cause a nonsampling error.

In reality, a sample will never be exactly representative of the population so there will always be some sampling error. As a rule, the larger the sample, the smaller the sampling error.

In statistics, a is created when a sample is collected from a population and some members of the population are not as likely to be chosen as others (remember, each member of the population should have an equally likely chance of being chosen). When a happens, there can be incorrect conclusions drawn about the population that is being studied.

Critical Evaluation

We need to evaluate the statistical studies we read about critically and analyze them before accepting the results of the studies. Common problems to be aware of include

  • Problems with samples: A sample must be representative of the population. A sample that is not representative of the population is biased. Biased samples that are not representative of the population give results that are inaccurate and not valid.
  • Self-selected samples: Responses only by people who choose to respond, such as call-in surveys, are often unreliable.
  • Sample size issues: Samples that are too small may be unreliable. Larger samples are better, if possible. In some situations, having small samples is unavoidable and can still be used to draw conclusions. Examples: crash testing cars or medical testing for rare conditions
  • Undue influence:  collecting data or asking questions in a way that influences the response
  • Non-response or refusal of subject to participate:  The collected responses may no longer be representative of the population.  Often, people with strong positive or negative opinions may answer surveys, which can affect the results.
  • Causality: A relationship between two variables does not mean that one causes the other to occur. They may be related (correlated) because of their relationship through a different variable.
  • Self-funded or self-interest studies: A study performed by a person or organization in order to support their claim. Is the study impartial? Read the study carefully to evaluate the work. Do not automatically assume that the study is good, but do not automatically assume the study is bad either. Evaluate it on its merits and the work done.
  • Misleading use of data: improperly displayed graphs, incomplete data, or lack of context
  • Confounding:  When the effects of multiple factors on a response cannot be separated.  Confounding makes it difficult or impossible to draw valid conclusions about the effect of each factor.

Collaborative Exercise

As a class, determine whether or not the following samples are representative. If they are not, discuss the reasons.

  1. To find the average GPA of all students in a university, use all honor students at the university as the sample.
  2. To find out the most popular cereal among young people under the age of ten, stand outside a large supermarket for three hours and speak to every twentieth child under age ten who enters the supermarket.
  3. To find the average annual income of all adults in the United States, sample U.S. Representatives. Create a cluster sample by considering each state as a stratum (group). By using simple random sampling, select states to be part of the cluster. Then survey every U.S. Representative in the cluster.
  4. To determine the proportion of people taking public transportation to work, survey 20 people in New York City. Conduct the survey by sitting in Central Park on a bench and interviewing every person who sits next to you.
  5. To determine the average cost of a two-day stay in a hospital in Massachusetts, survey 100 hospitals across the state using simple random sampling.

Example 1.11

Problem

A study is done to determine the average tuition that San Jose State undergraduate students pay per semester. Each student in the following samples is asked how much tuition they paid for the Fall semester. What is the type of sampling in each case?

  1. A sample of 100 undergraduate San Jose State students is taken by organizing the students’ names by classification (first-year, sophomore, junior, or senior), and then selecting 25 students from each.
  2. A random number generator is used to select a student from the alphabetical listing of all undergraduate students in the Fall semester. Starting with that student, every 50th student is chosen until 75 students are included in the sample.
  3. A completely random method is used to select 75 students. Each undergraduate student in the fall semester has the same probability of being chosen at any stage of the sampling process.
  4. The first-year, sophomore, junior, and senior years are numbered one, two, three, and four, respectively. A random number generator is used to pick two of those years. All students in those two years are in the sample.
  5. An administrative assistant is asked to stand in front of the library one Wednesday and to ask the first 100 undergraduate students he encounters what they paid for tuition the Fall semester. Those 100 students are the sample.

a. stratified; b. systematic; c. simple random; d. cluster; e. convenience

Try It 1.11

You are going to use the random number generator to generate different types of samples from the data.

This table displays six sets of quiz scores (each quiz counts 10 points) for an elementary statistics class.

#1 #2 #3 #4 #5 #6
5 7 10 9 8 3
10 5 9 8 7 6
9 10 8 6 7 9
9 10 10 9 8 9
7 8 9 5 7 4
9 9 9 10 8 7
7 7 10 9 8 8
8 8 9 10 8 8
9 7 8 7 7 8
8 8 10 9 8 7
Table 1.7

Instructions: Use the Random Number Generator to pick samples.

  1. Create a stratified sample by column. Pick three quiz scores randomly from each column.
    • Number each row one through ten.
    • On your calculator, press Math and arrow over to PRB.
    • For column 1, Press 5:randInt( and enter 1,10). Press ENTER. Record the number. Press ENTER 2 more times (even the repeats). Record these numbers. Record the three quiz scores in column one that correspond to these three numbers.
    • Repeat for columns two through six.
    • These 18 quiz scores are a stratified sample.
  2. Create a cluster sample by picking two of the columns. Use the column numbers: one through six.
    • Press MATH and arrow over to PRB.
    • Press 5:randInt( and enter 1,6). Press ENTER. Record the number. Press ENTER and record that number.
    • The two numbers are for two of the columns.
    • The quiz scores (20 of them) in these 2 columns are the cluster sample.
  3. Create a simple random sample of 15 quiz scores.
    • Use the numbering one through 60.
    • Press MATH. Arrow over to PRB. Press 5:randInt( and enter 1, 60).
    • Press ENTER 15 times and record the numbers.
    • Record the quiz scores that correspond to these numbers.
    • These 15 quiz scores are the random sample.
  4. Create a systematic sample of 12 quiz scores.
    • Use the numbering one through 60.
    • Press MATH. Arrow over to PRB. Press 5:randInt( and enter 1, 60).
    • Press ENTER. Record the number and the first quiz score. From that number, count ten quiz scores and record that quiz score. Keep counting ten quiz scores and recording the quiz score until you have a sample of 12 quiz scores. You may wrap around (go back to the beginning).

Example 1.12

Problem

Determine the type of sampling used (simple random, stratified, systematic, cluster, or convenience).

  1. A soccer coach selects six players from a group of boys aged eight to ten, seven players from a group of boys aged 11 to 12, and three players from a group of boys aged 13 to 14 to form a recreational soccer team.
  2. A pollster interviews all human resource personnel in five different high tech companies.
  3. A high school educational researcher interviews 50 public high school teachers and 50 private high school teachers.
  4. A medical researcher interviews every third patient from a list of patients at a local hospital.
  5. A high school counselor uses a computer to generate 50 random numbers and then picks students whose names correspond to the numbers.
  6. A student interviews classmates in their algebra class to determine how many pairs of jeans a student owns, on the average.

a. stratified; b. cluster; c. stratified; d. systematic; e. simple random; f.convenience

Try It 1.12

Determine the type of sampling used (simple random, stratified, systematic, cluster, or convenience).

A high school principal polls 50 first-year students, 50 sophomores, 50 juniors, and 50 seniors regarding policy changes for after school activities.

If we were to examine two samples representing the same population, even if we used random sampling methods for the samples, they would not be exactly the same. Just as there is variation in data, there is variation in samples. As you become accustomed to sampling, the variability will begin to seem natural.

NOTE

In Confidence Intervals of the text, sample size formulas are provided which will determine sample sizes when sampling from a population. The sample size will be a function of the desired precision and not a function of the population size. It may be somewhat counterintuitive that the sample size does not depend on the population size. However, this implies that a sample size of 1,000 can be adequate to represent a population of 100,000 versus 1,000,000 given that the same level of precision is desired. When working in Confidence Intervals with sample size formulas, the student will notice that population size is not a factor in determining the sample size.

Example 1.13

Suppose ABC College has 10,000 part-time students (the population). We are interested in the average amount of money a part-time student spends on books in the fall term. Asking all 10,000 students is an almost impossible task.

Suppose we take two different samples.

First, we use and survey ten students from a first term organic chemistry class. Many of these students are taking first term calculus in addition to the organic chemistry class. The amount of money they spend on books is as follows:

$128; $87; $173; $116; $130; $204; $147; $189; $93; $153

The second sample is taken using a list of senior citizens who take P.E. classes and taking every fifth senior citizen on the list, for a total of ten senior citizens. They spend:

$50; $40; $36; $15; $50; $100; $40; $53; $22; $22

It is unlikely that any student is in both samples.

Problem

a. Do you think that either of these samples is representative of (or is characteristic of) the entire 10,000 part-time student population?

a. No. The first sample probably consists of science-oriented students. Besides the chemistry course, some of them are also taking first-term calculus. Books for these classes tend to be expensive. Most of these students are, more than likely, paying more than the average part-time student for their books. The second sample is a group of senior citizens who are, more than likely, taking courses for health and interest. The amount of money they spend on books is probably much less than the average part-time student. Both samples are biased. Also, in both cases, not all students have a chance to be in either sample.

Problem

b. Since these samples are not representative of the entire population, is it wise to use the results to describe the entire population?

b. No. For these samples, each member of the population did not have an equally likely chance of being chosen.

Now, suppose we take a third sample. We choose ten different part-time students from the disciplines of chemistry, math, English, psychology, sociology, history, nursing, physical education, art, and early childhood development. (We assume that these are the only disciplines in which part-time students at ABC College are enrolled and that an equal number of part-time students are enrolled in each of the disciplines.) Each student is chosen using simple random sampling. Using a calculator, random numbers are generated and a student from a particular discipline is selected if they have a corresponding number. The students spend the following amounts:

$180; $50; $150; $85; $260; $75; $180; $200; $200; $150

Problem

c. Is the sample biased?

c. The sample is unbiased, but a larger sample would be recommended to increase the likelihood that the sample will be close to representative of the population. However, for a biased sampling technique, even a large sample runs the risk of not being representative of the population.

Students often ask if it is "good enough" to take a sample, instead of surveying the entire population. If the survey is done well, the answer is yes.

Try It 1.13

A local radio station has a fan of 20,000 listeners. The station wants to know if its audience would prefer more music or more talk shows. Asking all 20,000 listeners is an almost impossible task.

The station uses and surveys the first 200 people they meet at one of the station’s music concert events. 24 people said they’d prefer more talk shows, and 176 people said they’d prefer more music.

Do you think that this sample is representative of (or is characteristic of) the entire 20,000 listener population?

Variation in Data

Variation is present in any set of data. For example, 16-ounce cans of beverage may contain more or less than 16 ounces of liquid. In one study, eight 16-ounce cans were measured and produced the following amount (in ounces) of beverage:

15.8; 16.1; 15.2; 14.8; 15.8; 15.9; 16.0; 15.5

Measurements of the amount of beverage in a 16-ounce can may vary because different people make the measurements or because the exact amount, 16 ounces of liquid, was not put into the cans. Manufacturers regularly run tests to determine if the amount of beverage in a 16-ounce can falls within the desired range.

Be aware that as you take data, your data may vary somewhat from the data someone else is taking for the same purpose. This is completely natural. However, if two or more of you are taking the same data and get very different results, it is time for you and the others to reevaluate your data-taking methods and your accuracy.

Variation in Samples

It was mentioned previously that two or more samples from the same population, taken randomly, and having close to the same characteristics of the population will likely be different from each other. Suppose Doreen and Jung both decide to study the average amount of time students at their college sleep each night. Doreen and Jung each take samples of 500 students. Doreen uses systematic sampling and Jung uses cluster sampling. Doreen's sample will be different from Jung's sample. Even if Doreen and Jung used the same sampling method, in all likelihood their samples would be different. Neither would be wrong, however.

Think about what contributes to making Doreen’s and Jung’s samples different.

If Doreen and Jung took larger samples (i.e. the number of data values is increased), their sample results (the average amount of time a student sleeps) might be closer to the actual population average. But still, their samples would be, in all likelihood, different from each other. This variability in samples cannot be stressed enough.

Size of a Sample

The size of a sample (often called the number of observations) is important. The examples you have seen in this book so far have been small. Samples of only a few hundred observations, or even smaller, are sufficient for many purposes. In polling, samples that are from 1,200 to 1,500 observations are considered large enough and good enough if the survey is random and is well done. You will learn why when you study confidence intervals.

Be aware that many large samples are biased. For example, call-in surveys are invariably biased, because people choose to respond or not.

Collaborative Exercise

Divide into groups of two, three, or four. Your instructor will give each group one six-sided die. Try this experiment twice. Roll one fair die (six-sided) 20 times. Record the number of ones, twos, threes, fours, fives, and sixes you get in Table 1.8 and Table 1.9 (“frequency” is the number of times a particular face of the die occurs):

Face on Die Frequency
1
2
3
4
5
6
Table 1.8 First Experiment (20 rolls)
Face on Die Frequency
1
2
3
4
5
6
Table 1.9 Second Experiment (20 rolls)

Did the two experiments have the same results? Probably not. If you did the experiment a third time, do you expect the results to be identical to the first or second experiment? Why or why not?

Which experiment had the correct results? They both did. The job of the statistician is to see through the variability and draw appropriate conclusions.

2.4 Ethics

OpenStax · 2.4 Ethics ↗
Instructional page including learning objectives, examples, figures, source tables and questions. Site navigation and embedded media players are omitted; source media links remain available.

Learning Objectives

By the end of this section, you will be able to:

  • Discuss how research involving human subjects is regulated
  • Summarize the processes of informed consent and debriefing
  • Explain how research involving animal subjects is regulated

Today, scientists agree that good research is ethical in nature and is guided by a basic respect for human dignity and safety. However, as you will read in the feature box, this has not always been the case. Modern researchers must demonstrate that the research they perform is ethically sound. This section presents how ethical considerations affect the design and implementation of research conducted today.

Research Involving Human Participants

Any experiment involving the participation of human subjects is governed by extensive, strict guidelines designed to ensure that the experiment does not result in harm. Any research institution that receives federal support for research involving human participants must have access to an institutional review board (IRB). The IRB is a committee of individuals often made up of members of the institution’s administration, scientists, and community members (Figure 2.20). The purpose of the IRB is to review proposals for research that involves human participants. The IRB reviews these proposals with the principles mentioned above in mind, and generally, approval from the IRB is required in order for the experiment to proceed.

A photograph shows a group of people seated around tables in a meeting room.
Figure 2.20 — 2.4 Ethics

Figure 2.20 An institution’s IRB meets regularly to review experimental proposals that involve human participants. (credit: International Hydropower Association/Flickr)

Rose M. Spielman, William J. Jenkins, and Marilyn D. Lovett, Psychology 2E, OpenStax. (credit: International Hydropower Association/Flickr) · CC BY-NC-SA 4.0 · Original image ↗ · Access for free ↗

An institution’s IRB requires several components in any experiment it approves. For one, each participant must sign an informed consent form before they can participate in the experiment. An informed consent form provides a written description of what participants can expect during the experiment, including potential risks and implications of the research. It also lets participants know that their involvement is completely voluntary and can be discontinued without penalty at any time. Furthermore, the informed consent guarantees that any data collected in the experiment will remain completely confidential. In cases where research participants are under the age of 18, the parents or legal guardians are required to sign the informed consent form.

Link to Learning

View this example of a consent form to learn more.

While the informed consent form should be as honest as possible in describing exactly what participants will be doing, sometimes deception is necessary to prevent participants’ knowledge of the exact research question from affecting the results of the study. Deception involves purposely misleading experiment participants in order to maintain the integrity of the experiment, but not to the point where the deception could be considered harmful. For example, if we are interested in how our opinion of someone is affected by their attire, we might use deception in describing the experiment to prevent that knowledge from affecting participants’ responses. In cases where deception is involved, participants must receive a full debriefing upon conclusion of the study—complete, honest information about the purpose of the experiment, how the data collected will be used, the reasons why deception was necessary, and information about how to obtain additional information about the study.

Dig Deeper

Ethics and the Tuskegee Syphilis Study

Unfortunately, the ethical guidelines that exist for research today were not always applied in the past. In 1932, rural, Black men from Tuskegee, Alabama, were recruited to participate in an experiment conducted by the U.S. Public Health Service, with the aim of studying syphilis in Black men (Figure 2.21). In exchange for free medical care, meals, and burial insurance, 600 men agreed to participate in the study. A little more than half of the men tested positive for syphilis, and they served as the experimental group (given that the researchers could not randomly assign participants to groups, this represents a quasi-experiment). The remaining syphilis-free individuals served as the control group. However, those individuals that tested positive for syphilis were never informed that they had the disease.

While there was no treatment for syphilis when the study began, by 1947 penicillin was recognized as an effective treatment for the disease. Despite this, no penicillin was administered to the participants in this study, and the participants were not allowed to seek treatment at any other facilities if they continued in the study. Over the course of 40 years, many of the participants unknowingly spread syphilis to their wives (and subsequently their children born from their wives) and eventually died because they never received treatment for the disease. This study was discontinued in 1972 when the experiment was discovered by the national press (Tuskegee University, n.d.). The resulting outrage over the experiment led directly to the National Research Act of 1974 and the strict ethical guidelines for research on humans described in this chapter. Why is this study unethical? How were the men who participated and their families harmed as a function of this research?

A photograph shows a person administering an injection.
Figure 2.21 — 2.4 Ethics

Figure 2.21 A participant in the Tuskegee Syphilis Study receives an injection.

Rose M. Spielman, William J. Jenkins, and Marilyn D. Lovett, Psychology 2E, OpenStax. · CC BY-NC-SA 4.0 · Original image ↗ · Access for free ↗

Link to Learning

Visit this website about the Tuskegee Syphilis Study to learn more.

Research Involving Animal Subjects

Many psychologists conduct research involving animal subjects. Often, these researchers use rodents (Figure 2.22) or birds as the subjects of their experiments—the APA estimates that 90% of all animal research in psychology uses these species (American Psychological Association, n.d.). Because many basic processes in animals are sufficiently similar to those in humans, these animals are acceptable substitutes for research that would be considered unethical in human participants.

A photograph shows a rat.
Figure 2.22 — 2.4 Ethics

Figure 2.22 Rats, like the one shown here, often serve as the subjects of animal research.

Rose M. Spielman, William J. Jenkins, and Marilyn D. Lovett, Psychology 2E, OpenStax. · CC BY-NC-SA 4.0 · Original image ↗ · Access for free ↗

This does not mean that animal researchers are immune to ethical concerns. Indeed, the humane and ethical treatment of animal research subjects is a critical aspect of this type of research. Researchers must design their experiments to minimize any pain or distress experienced by animals serving as research subjects.

Whereas IRBs review research proposals that involve human participants, animal experimental proposals are reviewed by an Institutional Animal Care and Use Committee (IACUC). An IACUC consists of institutional administrators, scientists, veterinarians, and community members. This committee is with ensuring that all experimental proposals require the humane treatment of animal research subjects. It also conducts semi-annual inspections of all animal facilities to ensure that the research protocols are being followed. No animal research project can proceed without the committee’s approval.

2.3 Analyzing Findings

OpenStax · 2.3 Analyzing Findings ↗
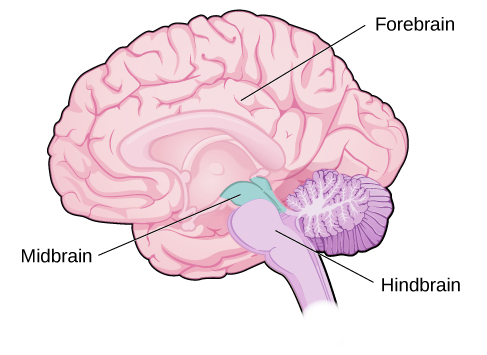
Instructional page including learning objectives, examples, figures, source tables and questions. Site navigation and embedded media players are omitted; source media links remain available.

Learning Objectives

By the end of this section, you will be able to:

  • Explain what a correlation coefficient tells us about the relationship between variables
  • Recognize that correlation does not indicate a cause-and-effect relationship between variables
  • Discuss our tendency to look for relationships between variables that do not really exist
  • Explain random sampling and assignment of participants into experimental and control groups
  • Discuss how experimenter or participant bias could affect the results of an experiment
  • Identify independent and dependent variables

Did you know that as sales in ice cream increase, so does the overall rate of crime? Is it possible that indulging in your favorite flavor of ice cream could send you on a crime spree? Or, after committing crime do you think you might decide to treat yourself to a cone? There is no question that a relationship exists between ice cream and crime (e.g., Harper, 2013), but it would be pretty foolish to decide that one thing actually caused the other to occur.

It is much more likely that both ice cream sales and crime rates are related to the temperature outside. When the temperature is warm, there are lots of people out of their houses, interacting with each other, getting annoyed with one another, and sometimes committing crimes. Also, when it is warm outside, we are more likely to seek a cool treat like ice cream. How do we determine if there is indeed a relationship between two things? And when there is a relationship, how can we discern whether it is attributable to coincidence or causation?

Correlational Research

Correlation means that there is a relationship between two or more variables (such as ice cream consumption and crime), but this relationship does not necessarily imply cause and effect. When two variables are correlated, it simply means that as one variable changes, so does the other. We can measure correlation by calculating a statistic known as a correlation coefficient. A correlation coefficient is a number from -1 to +1 that indicates the strength and direction of the relationship between variables. The correlation coefficient is usually represented by the letter r.

The number portion of the correlation coefficient indicates the strength of the relationship. The closer the number is to 1 (be it negative or positive), the more strongly related the variables are, and the more predictable changes in one variable will be as the other variable changes. The closer the number is to zero, the weaker the relationship, and the less predictable the relationship between the variables becomes. For instance, a correlation coefficient of 0.9 indicates a far stronger relationship than a correlation coefficient of 0.3. If the variables are not related to one another at all, the correlation coefficient is 0. The example above about ice cream and crime is an example of two variables that we might expect to have no relationship to each other.

The sign—positive or negative—of the correlation coefficient indicates the direction of the relationship (Figure 2.12). A positive correlation means that the variables move in the same direction. Put another way, it means that as one variable increases so does the other, and conversely, when one variable decreases so does the other. A negative correlation means that the variables move in opposite directions. If two variables are negatively correlated, a decrease in one variable is associated with an increase in the other and vice versa.

The example of ice cream and crime rates is a positive correlation because both variables increase when temperatures are warmer. Other examples of positive correlations are the relationship between an individual’s height and weight or the relationship between a person’s age and number of wrinkles. One might expect a negative correlation to exist between someone’s tiredness during the day and the number of hours they slept the previous night: the amount of sleep decreases as the feelings of tiredness increase. In a real-world example of negative correlation, student researchers at the University of Minnesota found a weak negative correlation (r = -0.29) between the average number of days per week that students got fewer than 5 hours of sleep and their GPA (Lowry, Dean, & Manders, 2010). Keep in mind that a negative correlation is not the same as no correlation. For example, we would probably find no correlation between hours of sleep and shoe size.

As mentioned earlier, correlations have predictive value. Imagine that you are on the admissions committee of a major university. You are faced with a huge number of applications, but you are able to accommodate only a small percentage of the applicant pool. How might you decide who should be admitted? You might try to correlate your current students’ college GPA with their scores on standardized tests like the SAT or ACT. By observing which correlations were strongest for your current students, you could use this information to predict relative success of those students who have applied for admission into the university.

Three scatterplots are shown. Scatterplot (a) is labeled “positive correlation” and shows scattered dots forming a rough line from the bottom left to the top right; the x-axis is labeled “weight” and the y-axis is labeled “height.” Scatterplot (b) is labeled “negative correlation” and shows scattered dots forming a rough line from the top left to the bottom right; the x-axis is labeled “tiredness” and the y-axis is labeled “hours of sleep.” Scatterplot (c) is labeled “no correlation” and shows scattered dots having no pattern; the x-axis is labeled “shoe size” and the y-axis is labeled “hours of sleep.”
Figure 2.12 — 2.3 Analyzing Findings
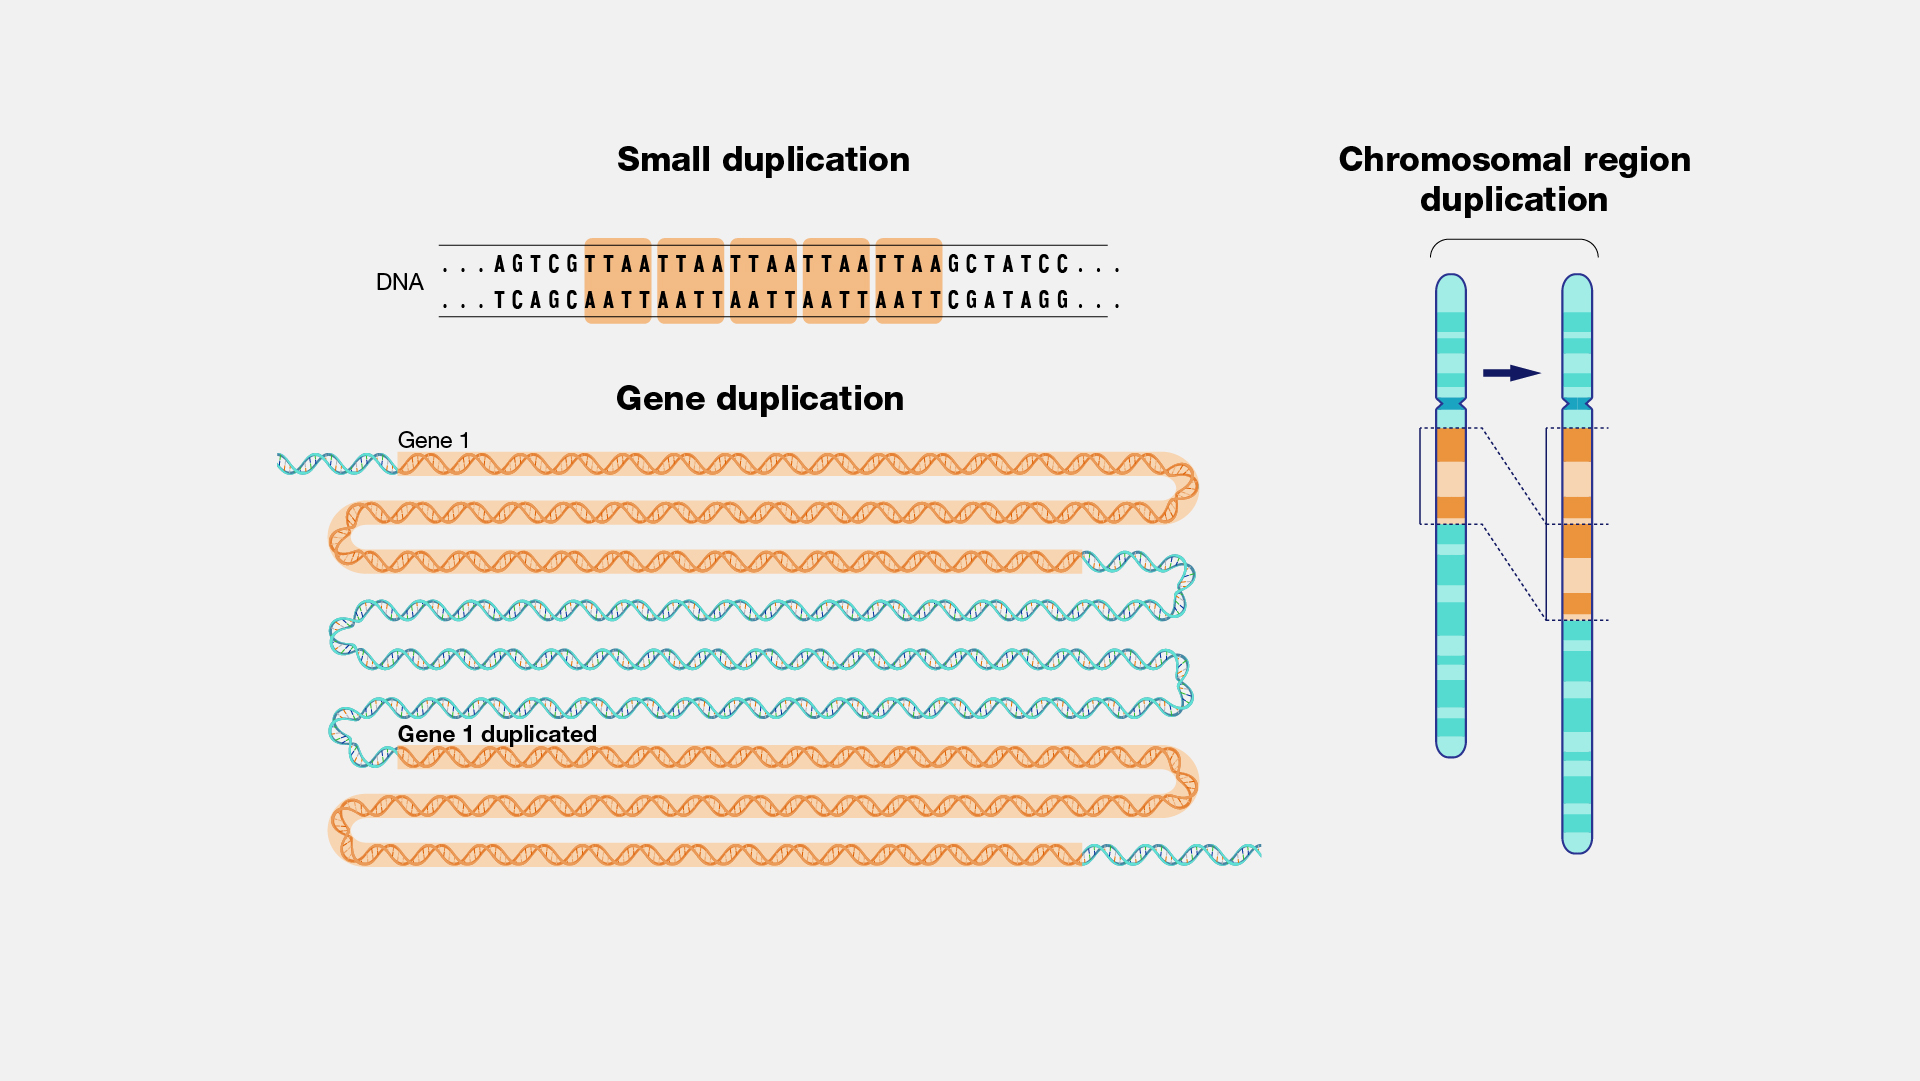
Figure 2.12 Scatterplots are a graphical view of the strength and direction of correlations. The stronger the correlation, the closer the data points are to a straight line. In these examples, we see that there is (a) a positive correlation between weight and height, (b) a negative correlation between tiredness and hours of sleep, and (c) no correlation between shoe size and hours of sleep.

Rose M. Spielman, William J. Jenkins, and Marilyn D. Lovett, Psychology 2E, OpenStax. · CC BY-NC-SA 4.0 · Original image ↗ · Access for free ↗

Link to Learning

Manipulate this interactive scatterplot to practice your understanding of positive and negative correlation.

Correlation Does Not Indicate Causation

Correlational research is useful because it allows us to discover the strength and direction of relationships that exist between two variables. However, correlation is limited because establishing the existence of a relationship tells us little about cause and effect. While variables are sometimes correlated because one does cause the other, it could also be that some other factor, a confounding variable, is actually causing the systematic movement in our variables of interest. In the ice cream/crime rate example mentioned earlier, temperature is a confounding variable that could account for the relationship between the two variables.

Even when we cannot point to clear confounding variables, we should not assume that a correlation between two variables implies that one variable causes changes in another. This can be frustrating when a cause-and-effect relationship seems clear and intuitive. Think back to our discussion of the research done by the American Society and how their research projects were some of the first demonstrations of the link between smoking and . It seems reasonable to assume that smoking causes , but if we were limited to correlational research, we would be overstepping our bounds by making this assumption.

Unfortunately, people mistakenly make claims of causation as a function of correlations all the time. Such claims are especially common in advertisements and news stories. For example, research found that people who eat certain breakfast cereal may have a reduced risk of heart disease (Anderson, Hanna, Peng, & Kryscio, 2000). Cereal companies are likely to share this information in a way that maximizes and perhaps overstates the positive aspects of eating cereal. But does cereal really cause better health, or are there other possible explanations for the health of those who eat cereal? While correlational research is invaluable in identifying relationships among variables, a major limitation is the inability to establish causality. Psychologists want to make statements about cause and effect, but the only way to do that is to conduct an experiment to answer a research question. The next section describes how scientific experiments incorporate methods that eliminate, or control for, alternative explanations, which allow researchers to explore how changes in one variable cause changes in another variable.

A photograph shows a bowl of cereal.
Figure 2.13 — 2.3 Analyzing Findings
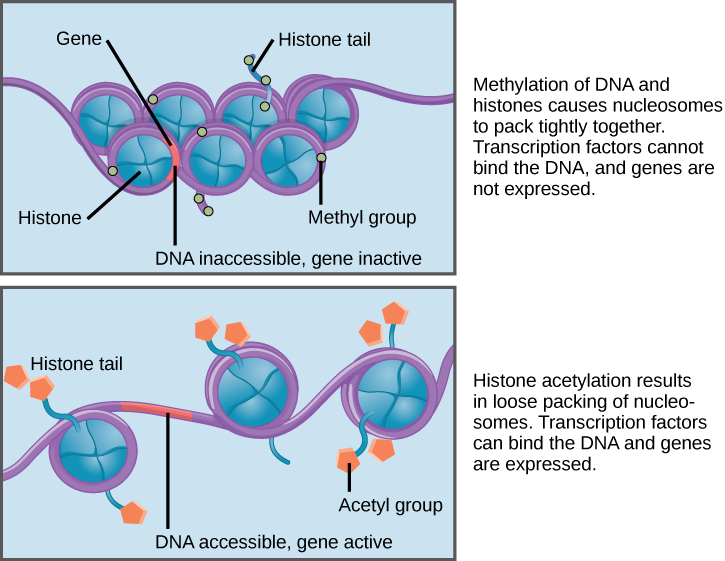
Figure 2.13 Does eating cereal really cause someone to be healthier? (credit: Tim Skillern)

Rose M. Spielman, William J. Jenkins, and Marilyn D. Lovett, Psychology 2E, OpenStax. (credit: Tim Skillern) · CC BY-NC-SA 4.0 · Original image ↗ · Access for free ↗

Illusory Correlations

The temptation to make erroneous cause-and-effect statements based on correlational research is not the only way we tend to misinterpret data. We also tend to make the mistake of illusory correlations, especially with unsystematic observations. Illusory correlations, or false correlations, occur when people believe that relationships exist between two things when no such relationship exists. One well-known illusory correlation is the supposed effect that the moon’s phases have on human behavior. Many people passionately assert that human behavior is affected by the phase of the moon, and specifically, that people act strangely when the moon is full (Figure 2.14).

A photograph shows the moon.
Figure 2.14 — 2.3 Analyzing Findings

Figure 2.14 Many people believe that a full moon makes people behave oddly. (credit: Cory Zanker)

Rose M. Spielman, William J. Jenkins, and Marilyn D. Lovett, Psychology 2E, OpenStax. (credit: Cory Zanker) · CC BY-NC-SA 4.0 · Original image ↗ · Access for free ↗

There is no denying that the moon exerts a powerful influence on our planet. The ebb and flow of the ocean’s tides are tightly tied to the gravitational forces of the moon. Many people believe, therefore, that it is logical that we are affected by the moon as well. After all, our bodies are largely made up of water. A meta-analysis of nearly 40 studies consistently demonstrated, however, that the relationship between the moon and our behavior does not exist (Rotton & Kelly, 1985). While we may pay more attention to odd behavior during the full phase of the moon, the rates of odd behavior remain constant throughout the lunar cycle.

Why are we so apt to believe in illusory correlations like this? Often we read or hear about them and simply accept the information as valid. Or, we have a hunch about how something works and then look for evidence to support that hunch, ignoring evidence that would tell us our hunch is false; this is known as . Other times, we find illusory correlations based on the information that comes most easily to mind, even if that information is severely limited. And while we may feel confident that we can use these relationships to better understand and predict the world around us, illusory correlations can have significant drawbacks. For example, research suggests that illusory correlations—in which certain behaviors are inaccurately attributed to certain groups—are involved in the formation of prejudicial attitudes that can ultimately lead to discriminatory behavior (Fiedler, 2004).

Causality: Conducting Experiments and Using the Data

As you’ve learned, the only way to establish that there is a cause-and-effect relationship between two variables is to conduct a scientific experiment. Experiment has a different meaning in the scientific context than in everyday life. In everyday conversation, we often use it to describe trying something for the first time, such as experimenting with a new hair style or a new food. However, in the scientific context, an experiment has precise requirements for design and implementation.

The Experimental Hypothesis

In order to conduct an experiment, a researcher must have a specific hypothesis to be tested. As you’ve learned, hypotheses can be formulated either through direct observation of the real world or after careful review of previous research. For example, if you think that the use of technology in the classroom has negative impacts on learning, then you have basically formulated a hypothesis—namely, that the use of technology in the classroom should be limited because it decreases learning. How might you have arrived at this particular hypothesis? You may have noticed that your classmates who take notes on their laptops perform at lower levels on class exams than those who take notes by hand, or those who receive a lesson via a computer program versus via an in-person teacher have different levels of performance when tested (Figure 2.15).

Many rows of students are in a classroom. One student has an open laptop on his desk.
Figure 2.15 — 2.3 Analyzing Findings

Figure 2.15 How might the use of technology in the classroom impact learning? (credit: modification of work by Nikolay Georgiev/Pixabay)

Rose M. Spielman, William J. Jenkins, and Marilyn D. Lovett, Psychology 2E, OpenStax. (credit: modification of work by Nikolay Georgiev/Pixabay) · CC BY-NC-SA 4.0 · Original image ↗ · Access for free ↗

These sorts of personal observations are what often lead us to formulate a specific hypothesis, but we cannot use limited personal observations and anecdotal evidence to rigorously test our hypothesis. Instead, to find out if real-world data supports our hypothesis, we have to conduct an experiment.

Designing an Experiment

The most basic experimental design involves two groups: the experimental group and the control group. The two groups are designed to be the same except for one difference— experimental manipulation. The experimental group gets the experimental manipulation—that is, the treatment or variable being tested (in this case, the use of technology)—and the control group does not. Since experimental manipulation is the only difference between the experimental and control groups, we can be sure that any differences between the two are due to experimental manipulation rather than chance.

In our example of how the use of technology should be limited in the classroom, we have the experimental group learn algebra using a computer program and then test their learning. We measure the learning in our control group after they are taught algebra by a teacher in a traditional classroom. It is important for the control group to be treated similarly to the experimental group, with the exception that the control group does not receive the experimental manipulation.

We also need to precisely define, or operationalize, how we measure learning of algebra. An is a precise description of our variables, and it is important in allowing others to understand exactly how and what a researcher measures in a particular experiment. In operationalizing learning, we might choose to look at performance on a test covering the material on which the individuals were taught by the teacher or the computer program. We might also ask our participants to summarize the information that was just presented in some way. Whatever we determine, it is important that we operationalize learning in such a way that anyone who hears about our study for the first time knows exactly what we mean by learning. This aids peoples’ ability to interpret our data as well as their capacity to repeat our experiment should they choose to do so.

Once we have operationalized what is considered use of technology and what is considered learning in our experiment participants, we need to establish how we will run our experiment. In this case, we might have participants spend 45 minutes learning algebra (either through a computer program or with an in-person math teacher) and then give them a test on the material covered during the 45 minutes.

Ideally, the people who score the tests are unaware of who was assigned to the experimental or control group, in order to control for experimenter bias. Experimenter bias refers to the possibility that a researcher’s expectations might skew the results of the study. Remember, conducting an experiment requires a lot of planning, and the people involved in the research project have a vested interest in supporting their hypotheses. If the observers knew which child was in which group, it might influence how they interpret ambiguous responses, such as sloppy handwriting or minor computational mistakes. By being blind to which child is in which group, we protect against those biases. This situation is a single-blind study, meaning that one of the groups (participants) are unaware as to which group they are in (experiment or control group) while the researcher who developed the experiment knows which participants are in each group.

In a double-blind study, both the researchers and the participants are blind to group assignments. Why would a researcher want to run a study where no one knows who is in which group? Because by doing so, we can control for both experimenter and participant expectations. If you are familiar with the phrase placebo effect, you already have some idea as to why this is an important consideration. The placebo effect occurs when people's expectations or beliefs influence or determine their experience in a given situation. In other words, simply expecting something to happen can actually make it happen.

The placebo effect is commonly described in terms of testing the effectiveness of a new medication. Imagine that you work in a pharmaceutical company, and you think you have a new drug that is effective in treating depression. To demonstrate that your medication is effective, you run an experiment with two groups: The experimental group receives the medication, and the control group does not. But you don’t want participants to know whether they received the drug or not.

Why is that? Imagine that you are a participant in this study, and you have just taken a pill that you think will improve your mood. Because you expect the pill to have an effect, you might feel better simply because you took the pill and not because of any drug actually contained in the pill—this is the placebo effect.

To make sure that any effects on mood are due to the drug and not due to expectations, the control group receives a placebo (in this case a sugar pill). Now everyone gets a pill, and once again neither the researcher nor the experimental participants know who got the drug and who got the sugar pill. Any differences in mood between the experimental and control groups can now be attributed to the drug itself rather than to experimenter bias or participant expectations (Figure 2.16).

A photograph shows three glass bottles of pills labeled as placebos.
Figure 2.16 — 2.3 Analyzing Findings
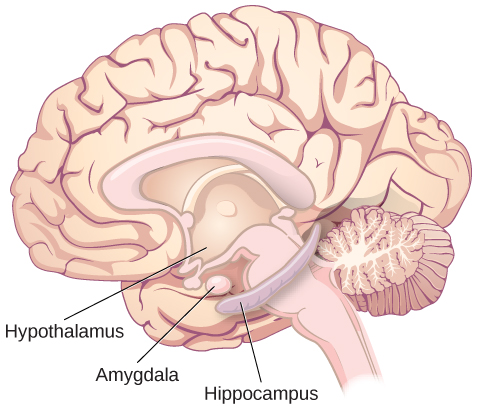
Figure 2.16 Providing the control group with a placebo treatment protects against bias caused by expectancy. (credit: Elaine and Arthur Shapiro)

Rose M. Spielman, William J. Jenkins, and Marilyn D. Lovett, Psychology 2E, OpenStax. (credit: Elaine and Arthur Shapiro) · CC BY-NC-SA 4.0 · Original image ↗ · Access for free ↗

Independent and Dependent Variables

In a research experiment, we strive to study whether changes in one thing cause changes in another. To achieve this, we must pay attention to two important variables, or things that can be changed, in any experimental study: the and the . An is manipulated or controlled by the experimenter. In a well-designed experimental study, the is the only important difference between the experimental and control groups. In our example of how technology use in the classroom affects learning, the is the type of learning by participants in the study (Figure 2.17). A is what the researcher measures to see how much effect the had. In our example, the is the learning exhibited by our participants.

A box labeled “independent variable: taking notes on a laptop or by hand” contains a photograph of a classroom of students with an open laptop on one student's desk. An arrow labeled “influences change in the…” leads to a second box. The second box is labeled “dependent variable: performance on measure of learning” and has a photograph of a student at a desk, taking a test.
Figure 2.17 — 2.3 Analyzing Findings
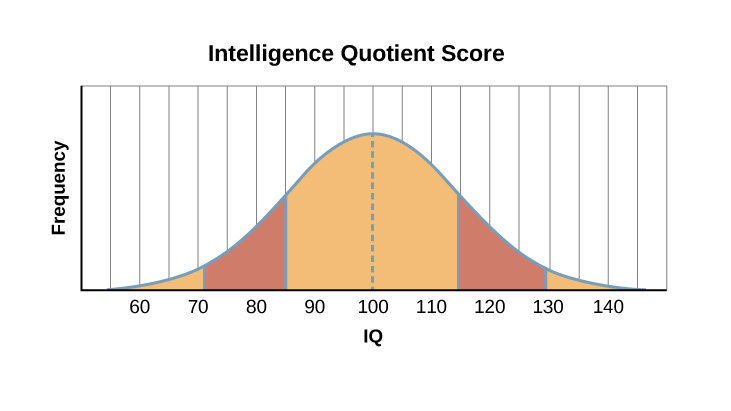
Figure 2.17 In an experiment, manipulations of the independent variable are expected to result in changes in the dependent variable. (credit: “classroom” modification of work by Nikolay Georgiev/Pixabay; credit “note taking”: modification of work by KF/Wikimedia)

Rose M. Spielman, William J. Jenkins, and Marilyn D. Lovett, Psychology 2E, OpenStax. (credit: “classroom” modification of work by Nikolay Georgiev/Pixabay; credit “note taking”: modification of work by KF/Wikimedia) · CC BY-NC-SA 4.0 · Original image ↗ · Access for free ↗

We expect that the will change as a function of the . In other words, the depends on the . A good way to think about the relationship between the independent and dependent variables is with this question: What effect does the have on the ? Returning to our example, what is the effect of being taught a lesson through a computer program versus through an in-person instructor?

Selecting and Assigning Experimental Participants

Now that our study is designed, we need to obtain a sample of individuals to include in our experiment. Our study involves human participants so we need to determine whom to include. Participants are the subjects of psychological research, and as the name implies, individuals who are involved in psychological research actively participate in the process. Often, psychological research projects rely on college students to serve as participants. In , the vast majority of research in psychology subfields has historically involved students as research participants (Sears, 1986; Arnett, 2008). But are college students truly representative of the general population? College students tend to be younger, more educated, more liberal, and less diverse than the general population. Although using students as test subjects is an accepted practice, relying on such a limited pool of research participants can be problematic because it is difficult to generalize findings to the larger population.

Our hypothetical experiment involves high school students, and we must first generate a sample of students. Samples are used because populations are usually too large to reasonably involve every member in our particular experiment (Figure 2.18). If possible, we should use a random sample (there are other types of samples, but for the purposes of this chapter, we will focus on random samples). A random sample is a subset of a larger population in which every member of the population has an equal chance of being selected. Random samples are preferred because if the sample is large enough we can be reasonably sure that the participating individuals are representative of the larger population. This means that the percentages of characteristics in the sample—sex, , socioeconomic level, and any other characteristics that might affect the results—are close to those percentages in the larger population.

In our example, let’s say we decide our population of interest is algebra students. But all algebra students is a very large population, so we need to be more specific; instead we might say our population of interest is all algebra students in a particular city. We should include students from various income brackets, family situations, races, ethnicities, religions, and geographic areas of town. With this more manageable population, we can work with the local schools in selecting a random sample of around 200 algebra students who we want to participate in our experiment.

In summary, because we cannot test all of the algebra students in a city, we want to find a group of about 200 that reflects the composition of that city. With a representative group, we can generalize our findings to the larger population without fear of our sample being biased in some way.

(a) A photograph shows an aerial view of crowds on a street. (b) A photograph shows s small group of children.
Figure 2.18 — 2.3 Analyzing Findings

Figure 2.18 Researchers may work with (a) a large population or (b) a sample group that is a subset of the larger population. (credit “crowd”: modification of work by James Cridland; credit “students”: modification of work by Laurie Sullivan)

Rose M. Spielman, William J. Jenkins, and Marilyn D. Lovett, Psychology 2E, OpenStax. (credit “crowd”: modification of work by James Cridland; credit “students”: modification of work by Laurie Sullivan) · CC BY-NC-SA 4.0 · Original image ↗ · Access for free ↗

Now that we have a sample, the next step of the experimental process is to split the participants into experimental and control groups through . With , all participants have an equal chance of being assigned to either group. There is statistical software that will randomly assign each of the algebra students in the sample to either the experimental or the control group.

is critical for sound experimental design. With sufficiently large samples, makes it unlikely that there are systematic differences between the groups. So, for instance, it would be very unlikely that we would get one group composed entirely of males, a given ethnic identity, or a given religious ideology. This is important because if the groups were systematically different before the experiment began, we would not know the origin of any differences we find between the groups: Were the differences preexisting, or were they caused by manipulation of the ? allows us to assume that any differences observed between experimental and control groups result from the manipulation of the .

Link to Learning

Use this online random number generator to learn more about random sampling and assignments.

Issues to Consider

While experiments allow scientists to make cause-and-effect claims, they are not without problems. True experiments require the experimenter to manipulate an , and that can complicate many questions that psychologists might want to address. For instance, imagine that you want to know what effect sex (the ) has on spatial memory (the ). Although you can certainly look for differences between males and females on a task that taps into spatial memory, you cannot directly control a person’s sex. We categorize this type of research approach as quasi-experimental and recognize that we cannot make cause-and-effect claims in these circumstances.

Experimenters are also limited by ethical constraints. For instance, you would not be able to conduct an experiment designed to determine if experiencing abuse as a child leads to lower levels of among adults. To conduct such an experiment, you would need to randomly assign some experimental participants to a group that receives abuse, and that experiment would be unethical.

Interpreting Experimental Findings

Once data is collected from both the experimental and the control groups, a statistical analysis is conducted to find out if there are meaningful differences between the two groups. A statistical analysis determines how likely it is that any difference found is due to chance (and thus not meaningful). For example, if an experiment is done on the effectiveness of a nutritional supplement, and those taking a placebo pill (and not the supplement) have the same result as those taking the supplement, then the experiment has shown that the nutritional supplement is not effective. Generally, psychologists consider differences to be statistically significant if there is less than a five percent chance of observing them if the groups did not actually differ from one another. Stated another way, psychologists want to limit the chances of making “false positive” claims to five percent or less.

The greatest strength of experiments is the ability to assert that any significant differences in the findings are caused by the . This occurs because random selection, , and a design that limits the effects of both experimenter bias and participant expectancy should create groups that are similar in composition and treatment. Therefore, any difference between the groups is attributable to the , and now we can finally make a causal statement. If we find that watching a violent television program results in more violent behavior than watching a nonviolent program, we can safely say that watching violent television programs causes an increase in the display of violent behavior.

Reporting Research

When psychologists complete a research project, they generally want to share their findings with other scientists. The American Psychological Association (APA) publishes a manual detailing how to write a paper for submission to scientific journals. Unlike an article that might be published in a magazine like Psychology Today, which targets a general audience with an interest in psychology, scientific journals generally publish peer-reviewed journal articles aimed at an audience of professionals and scholars who are actively involved in research themselves.

Link to Learning

The Online Writing Lab (OWL) at Purdue University can walk you through the APA writing guidelines.

A peer-reviewed journal article is read by several other scientists (generally anonymously) with expertise in the subject matter. These peer reviewers provide feedback—to both the author and the journal editor—regarding the quality of the draft. Peer reviewers look for a strong rationale for the research being described, a clear description of how the research was conducted, and evidence that the research was conducted in an ethical manner. They also look for flaws in the study's design, methods, and statistical analyses. They check that the conclusions drawn by the authors seem reasonable given the observations made during the research. Peer reviewers also comment on how valuable the research is in advancing the discipline’s knowledge. This helps prevent unnecessary of research findings in the scientific literature and, to some extent, ensures that each research article provides new information. Ultimately, the journal editor will compile all of the peer reviewer feedback and determine whether the article will be published in its current state (a rare occurrence), published with revisions, or not accepted for publication.

Peer review provides some degree of quality control for psychological research. Poorly conceived or executed studies can be weeded out, and even well-designed research can be improved by the revisions suggested. Peer review also ensures that the research is described clearly enough to allow other scientists to replicate it, meaning they can repeat the experiment using different samples to determine . Sometimes replications involve additional measures that expand on the original finding. In any case, each serves to provide more evidence to support the original research findings. Successful replications of published research make scientists more apt to adopt those findings, while repeated failures tend to cast doubt on the legitimacy of the original article and lead scientists to look elsewhere. For example, it would be a major advancement in the medical field if a published study indicated that taking a new drug helped individuals achieve better health without changing their behavior. But if other scientists could not replicate the results, the original study’s claims would be questioned.

In recent years, there has been increasing concern about a “ crisis” that has affected a number of scientific fields, including psychology. Some of the most well-known studies and scientists have produced research that has failed to be replicated by others (as discussed in Shrout & Rodgers, 2018). In , even a famous Nobel Prize-winning scientist has recently retracted a published paper because she had difficulty replicating her results (Nobel Prize-winning scientist Frances Arnold retracts paper, 2020 January 3). These kinds of outcomes have prompted some scientists to begin to work together and more openly, and some would argue that the current “crisis” is actually improving the ways in which science is conducted and in how its results are shared with others (Aschwanden, 2018).

Dig Deeper

The Vaccine-Autism Myth and Retraction of Published Studies

Some scientists have claimed that routine childhood vaccines cause some children to develop autism, and, in , several peer-reviewed publications published research making these claims. Since the initial reports, large-scale epidemiological research has indicated that vaccinations are not responsible for causing autism and that it is much safer to have your child vaccinated than not. Furthermore, several of the original studies making this claim have since been retracted.

A published piece of work can be rescinded when data is called into question because of falsification, fabrication, or serious research design problems. Once rescinded, the scientific community is informed that there are serious problems with the original publication. Retractions can be initiated by the researcher who led the study, by research collaborators, by the institution that employed the researcher, or by the editorial board of the journal in which the article was originally published. In the vaccine-autism case, the retraction was made because of a significant conflict of interest in which the leading researcher had a financial interest in establishing a link between childhood vaccines and autism (Offit, 2008). Unfortunately, the initial studies received so much media attention that many parents around the world became hesitant to have their children vaccinated (Figure 2.19). Continued reliance on such debunked studies has significant consequences. For instance, between January and October of 2019, there were 22 measles outbreaks across the United States and more than a thousand cases of individuals contracting measles (Patel et al., 2019). This is likely due to the anti-vaccination movements that have risen from the debunked research. For more information about how the vaccine/autism story unfolded, as well as the repercussions of this story, take a look at Paul Offit’s book, Autism’s False Prophets: Bad Science, Risky Medicine, and the Search for a Cure.

A photograph shows a child being given an oral vaccine.
Figure 2.19 — 2.3 Analyzing Findings

Figure 2.19 Some people still think vaccinations cause autism. (credit: modification of work by UNICEF Sverige)

Rose M. Spielman, William J. Jenkins, and Marilyn D. Lovett, Psychology 2E, OpenStax. (credit: modification of work by UNICEF Sverige) · CC BY-NC-SA 4.0 · Original image ↗ · Access for free ↗

and

and are two important considerations that must be made with any type of data collection. refers to the ability to consistently produce a given result. In the context of psychological research, this would mean that any instruments or tools used to collect data do so in consistent, reproducible ways. There are a number of different types of . Some of these include inter-rater (the degree to which two or more different observers agree on what has been observed), internal consistency (the degree to which different items on a survey that measure the same thing correlate with one another), and test-retest (the degree to which the outcomes of a particular measure remain consistent over multiple administrations).

Unfortunately, being consistent in measurement does not necessarily mean that you have measured something correctly. To illustrate this concept, consider a kitchen scale that would be used to measure the weight of cereal that you eat in the morning. If the scale is not properly , it may consistently under- or overestimate the amount of cereal that’s being measured. While the scale is highly reliable in producing consistent results (e.g., the same amount of cereal poured onto the scale produces the same reading each time), those results are incorrect. This is where comes into play. refers to the extent to which a given instrument or tool accurately measures what it’s supposed to measure, and once again, there are a number of ways in which can be expressed. Ecological (the degree to which research results generalize to real-world applications), construct (the degree to which a given variable actually captures or measures what it is intended to measure), and face (the degree to which a given variable seems valid on the surface) are just a few types that researchers consider. While any valid measure is by necessity reliable, the reverse is not necessarily true. Researchers strive to use instruments that are both highly reliable and valid.

Everyday Connection

How Valid Are the SAT and ACT?

Standardized tests like the SAT and ACT are supposed to measure an individual’s aptitude for a college education, but how reliable and valid are such tests? Research conducted by the College Board suggests that scores on the SAT have high predictive for first-year college students’ GPA (Kobrin, Patterson, Shaw, Mattern, & Barbuti, 2008). In this context, predictive refers to the test’s ability to effectively predict the GPA of college freshmen. Given that many institutions of higher education require the SAT or ACT for admission, this high degree of predictive might be comforting.

However, the emphasis placed on SAT or ACT scores in college admissions is changing based on a number of factors. For one, some researchers assert that these tests are biased, and students from historically marginalized populations are at a disadvantage that unfairly reduces the likelihood of being admitted into a college (Santelices & Wilson, 2010). Additionally, some research has suggested that the predictive of these tests is grossly exaggerated in how well they are able to predict the GPA of first-year college students. In , it has been suggested that the SAT’s predictive may be overestimated by as much as 150% (Rothstein, 2004). Many institutions of higher education are beginning to consider de-emphasizing the significance of SAT scores in making admission decisions (Rimer, 2008).

Recent examples of high profile cheating scandals both domestically and abroad have only increased the scrutiny being placed on these types of tests, and as of March 2019, more than 1000 institutions of higher education have either relaxed or eliminated the requirements for SAT or ACT testing for admissions (Strauss, 2019, March 19).